[CloudNeta] Hands-On LLM Serving 6주차 part 1 - Scaling LLM Inference with vLLM and AWS Tranium Workshop
이 글은 6주차 연재의 첫 번째 글입니다.
- part 1 - Scaling LLM Inference with vLLM and AWS Tranium Workshop (현재 글)
들어가며
Lab 1: EKS 클러스터 설정
사전준비
아래 명령어로 환경구성을 진행합니다.
#
cd workshop
pwd

# Update package list and install tools
#   커널 재부팅이 있으니 진행합시다. 바로 진행되네요
echo "Updating package list and installing tools..."
sudo apt update
sudo apt install -y python3-pip jq unzip

# Install AWS CLI v2
#   별 문제없이 잘 됩니다
echo "Installing AWS CLI v2..."
curl "https://awscli.amazonaws.com/awscli-exe-linux-x86_64.zip" -o "awscliv2.zip"
unzip awscliv2.zip
sudo ./aws/install --update

# Install Helm
#   헬름 설치도 잘 되고요
echo "Installing Helm..."
curl https://raw.githubusercontent.com/helm/helm/main/scripts/get-helm-3 | bash

# Enable kubectl autocompletion for current session and add to bashrc
echo "Setting up kubectl autocompletion..."
source <(kubectl completion bash) && echo "source <(kubectl completion bash)" >> ~/.bashrc

# Verify installations
echo "Verifying installations..."
aws --version
helm version --short
jq --version
echo "kubectl autocompletion enabled!"
이런 식으로 잘 되는 것을 볼 수 있습니다.
ubuntu@ip-10-0-1-41:~/workshop$ echo "Verifying installations..."
aws --version
helm version --short
jq --version
echo "kubectl autocompletion enabled!"
Verifying installations...
aws-cli/2.36.44 Python/3.14.6 Linux/6.8.0-1035-aws exe/x86_64.ubuntu.22
v3.22.0+g144ca65
jq-1.6
kubectl autocompletion enabled!
이어서 환경변수 세팅을 합시다. 꼭 해주고 넘어가야하니 참고해주세요
export AWS_REGION=us-west-2
export CLUSTER_NAME=ai-infra-summit-test-cluster
export EKS_VERSION=1.33
export INSTANCE_TYPE=trn1.2xlarge
export DESIRED_NODES=1
export WORKER_AMI=$(aws ssm get-parameter \
    --name /aws/service/eks/optimized-ami/1.33/amazon-linux-2023/x86_64/neuron/recommended/image_id \
    --region $AWS_REGION \
    --query "Parameter.Value" \
    --output text)
export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
export BUCKET_NAME=ai-infra-summit-vllm-models-cache-${AWS_ACCOUNT_ID}

echo "$CLUSTER_NAME $WORKER_AMI $AWS_ACCOUNT_ID $BUCKET_NAME"
잘 되네요!
echo "$CLUSTER_NAME $WORKER_AMI $AWS_ACCOUNT_ID $BUCKET_NAME"
ai-infra-summit-test-cluster ami-REDACTED REDACTED ai-infra-summit-vllm-models-cache-REDACTED
클러스터 접근 설정
aws eks update-kubeconfig 으로 접근권한을 얻은 후 파드와 클러스터 정보를 확인해봅시다.
$ ubuntu@ip-10-0-1-41:~/workshop$ aws eks update-kubeconfig --region $AWS_REGION --name $CLUSTER_NAME
Added new context arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster to /home/ubuntu/.kube/config

$ ubuntu@ip-10-0-1-41:~/workshop$ cat ~/.kube/config
apiVersion: v1
clusters:
- cluster:
    certificate-authority-data: <REDACTED>
    server: https://D5758DECBE4C8436A000042718FC282D.gr7.us-west-2.eks.amazonaws.com
  name: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
contexts:
- context:
    cluster: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
    user: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
  name: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
current-context: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
kind: Config
preferences: {}
users:
- name: arn:aws:eks:us-west-2:<REDACTED>:cluster/ai-infra-summit-test-cluster
  user:
    exec:
      apiVersion: client.authentication.k8s.io/v1beta1
      args:
      - --region
      - us-west-2
      - eks
      - get-token
      - --cluster-name
      - ai-infra-summit-test-cluster
      - --output
      - json
      command: aws
현황을 봅시다.
$ ubuntu@ip-10-0-1-41:~/workshop$ kubectl get pod -A
NAMESPACE     NAME                       READY   STATUS    RESTARTS   AGE
kube-system   coredns-75cb89d95b-gmbhv   0/1     Pending   0          37h
kube-system   coredns-75cb89d95b-tht4q   0/1     Pending   0          37h

$ ubuntu@ip-10-0-1-41:~/workshop$ kubectl cluster-info
Kubernetes control plane is running at https://REDACTED.gr7.us-west-2.eks.amazonaws.com
CoreDNS is running at https://REDACTED.gr7.us-west-2.eks.amazonaws.com/api/v1/namespaces/kube-system/services/kube-dns:dns/proxy

To further debug and diagnose cluster problems, use 'kubectl cluster-info dump'.
이후 k9s 를 설치합니다.
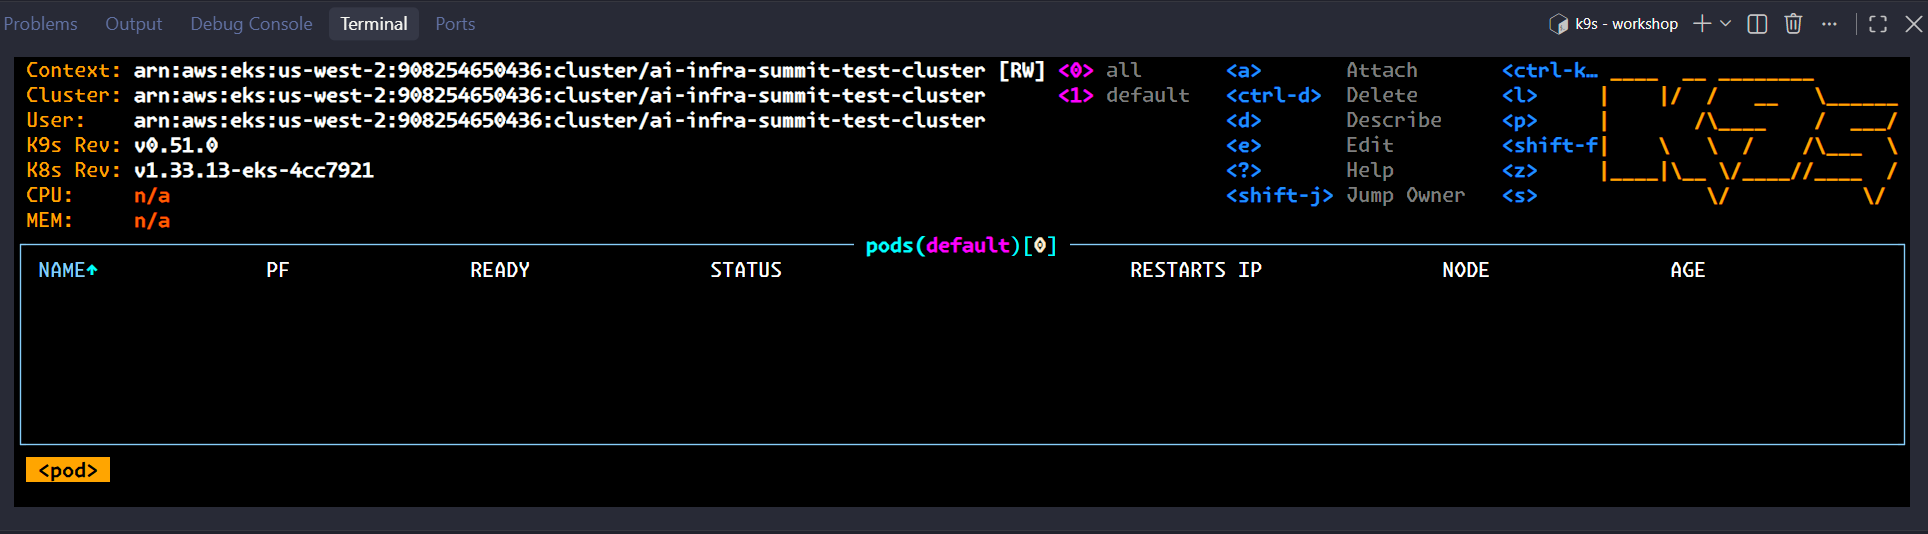
클러스터 네트워킹 설정
이후 노드 접근작업의 편의를 위해 ssh 키를 추가하고, 클러스터 네트워킹 설정을 합시다.
# Get VPC and create public subnets for trn1.2xlarge instances
VPC_ID=$(aws eks describe-cluster --name $CLUSTER_NAME --region $AWS_REGION --query 'cluster.resourcesVpcConfig.vpcId' --output text)
PUBLIC_ROUTE_TABLE=$(aws ec2 describe-route-tables --filters "Name=vpc-id,Values=$VPC_ID" "Name=route.destination-cidr-block,Values=0.0.0.0/0" --query 'RouteTables[0].RouteTableId' --output text)
echo "$VPC_ID $PUBLIC_ROUTE_TABLE"
vpc-06cda06a1da780126 rtb-0d694588705be058d
# Get supported AZs for instance type
SUPPORTED_AZS=($(aws ec2 describe-instance-type-offerings --location-type availability-zone --filters "Name=instance-type,Values=$INSTANCE_TYPE" --query 'InstanceTypeOfferings[*].Location' --output text))
echo "SUPPORTED_AZS" $SUPPORTED_AZS
SUPPORTED_AZS us-west-2b
# Get public subnets in supported AZs
VALID_SUBNETS=()
for az in "${SUPPORTED_AZS[@]}"; do
  subnet=$(aws ec2 describe-subnets --filters "Name=vpc-id,Values=$VPC_ID" "Name=map-public-ip-on-launch,Values=true" "Name=availability-zone,Values=$az" --query 'Subnets[0].SubnetId' --output text)
  [ "$subnet" != "None" ] && [ "$subnet" != "" ] && VALID_SUBNETS+=("$subnet")
done
echo ${VALID_SUBNETS[0]}
echo ${VALID_SUBNETS[1]}
subnet-028a53e0105798217
subnet-01e93e746cefe4850
# Ensure we have at least 2 subnets
[ ${#VALID_SUBNETS[@]} -lt 2 ] && { echo "Error: Need at least 2 public subnets in AZs that support $INSTANCE_TYPE"; exit 1; }
#   에러 없이 아무것도 안 나오니까 잘 됐습니다.
# Get first two valid subnets and their AZs
PUBLIC_SUBNET_1=${VALID_SUBNETS[0]}
PUBLIC_SUBNET_2=${VALID_SUBNETS[1]}
AZ_1=$(aws ec2 describe-subnets --subnet-ids $PUBLIC_SUBNET_1 --query 'Subnets[0].AvailabilityZone' --output text)
AZ_2=$(aws ec2 describe-subnets --subnet-ids $PUBLIC_SUBNET_2 --query 'Subnets[0].AvailabilityZone' --output text)
echo $AZ_1 $AZ_2
us-west-2b us-west-2d
성공적으로 나오는 걸 확인할 수 있습니다.
echo "Using PUBLIC_SUBNET_1: $PUBLIC_SUBNET_1 in $AZ_1"
echo "Using PUBLIC_SUBNET_2: $PUBLIC_SUBNET_2 in $AZ_2"
Using PUBLIC_SUBNET_1: subnet-028a53e0105798217 in us-west-2b
Using PUBLIC_SUBNET_2: subnet-01e93e746cefe4850 in us-west-2d
노드그룹 배포
이어서 아래 파일을 생성하고 노드그룹을 배포해봅시다.
apiVersion: eksctl.io/v1alpha5
kind: ClusterConfig
metadata:
  name: ai-infra-summit-test-cluster
  region: us-west-2
  version: "1.33"
vpc:
  id: vpc-06cda06a1da780126
  subnets:
    public:
      us-west-2b: { id: subnet-028a53e0105798217 }
      us-west-2d: { id: subnet-01e93e746cefe4850 }
  securityGroup: sg-0c7922b1a936bdcbd
managedNodeGroups:
- name: neuron-trn1-2x
  ami: ami-0e08c07b0376ba3f8
  amiFamily: AmazonLinux2023
  subnets: ["subnet-028a53e0105798217", "subnet-01e93e746cefe4850"]
  iam:
    attachPolicyARNs:
    - arn:aws:iam::aws:policy/AmazonEKSWorkerNodePolicy
    - arn:aws:iam::aws:policy/AmazonEC2ContainerRegistryReadOnly
    - arn:aws:iam::aws:policy/AmazonSSMManagedInstanceCore
    - arn:aws:iam::aws:policy/AmazonS3FullAccess
    - arn:aws:iam::aws:policy/AmazonEKS_CNI_Policy
  instanceType: trn1.2xlarge
  desiredCapacity: 1
  volumeSize: 100
  volumeType: gp2
  ssh:
     allow: true
     publicKeyPath: ~/.ssh/id_rsa.pub
ubuntu@ip-10-0-1-41:~/workshop$ eksctl create nodegroup --config-file=eks_nodegroup.yaml
2026-09-12 18:30:40 [!]  no eksctl-managed CloudFormation stacks found for "ai-infra-summit-test-cluster", will attempt to create nodegroup(s) on non eksctl-managed cluster
2026-09-12 18:30:40 [ℹ]  nodegroup "neuron-trn1-2x" will use "ami-0e08c07b0376ba3f8" [AmazonLinux2023/1.33]
2026-09-12 18:30:41 [ℹ]  using SSH public key "/home/ubuntu/.ssh/id_rsa.pub" as "eksctl-ai-infra-summit-test-cluster-nodegroup-neuron-trn1-2x-4e:6c:aa:e7:97:66:5b:1b:d9:b3:5f:c9:c8:cf:3b:79"
2026-09-12 18:30:41 [ℹ]  1 nodegroup (neuron-trn1-2x) was included (based on the include/exclude rules)
2026-09-12 18:30:41 [ℹ]  will create a CloudFormation stack for each of 1 managed nodegroups in cluster "ai-infra-summit-test-cluster"
2026-09-12 18:30:41 [ℹ]  1 task: { 1 task: { 1 task: { create managed nodegroup "neuron-trn1-2x" } } }
2026-09-12 18:30:41 [ℹ]  building managed nodegroup stack "eksctl-ai-infra-summit-test-cluster-nodegroup-neuron-trn1-2x"
2026-09-12 18:30:41 [ℹ]  deploying stack "eksctl-ai-infra-summit-test-cluster-nodegroup-neuron-trn1-2x"
2026-09-12 18:30:41 [ℹ]  waiting for CloudFormation stack "eksctl-ai-infra-summit-test-cluster-nodegroup-neuron-trn1-2x"

...
잘 떴으니 이를 확인하고
ubuntu@ip-10-0-1-41:~/workshop$ k get nodes -o wide
NAME                                      STATUS   ROLES    AGE   VERSION                INTERNAL-IP   EXTERNAL-IP     OS-IMAGE            KERNEL-VERSION                     CONTAINER-RUNTIME
ip-10-0-2-86.us-west-2.compute.internal   Ready    <none>   14m   v1.33.13-eks-cb19647   10.0.2.86     44.243.86.194   Amazon Linux 2023.12.20260831   6.12.103-127.188.amzn2023.x86_64   containerd://2.2.5+unknown
neuron 디바이스 플러그인을 확인합니다.
ubuntu@ip-10-0-1-41:~/workshop$ k get pods -n kube-system | grep neuron
neuron-device-plugin-tb42j   1/1     Running   0          13m
k describe pod -n kube-system -l name=neuron-device-plugin-ds
Name:                 neuron-device-plugin-tb42j
Namespace:            kube-system
Priority:             2000001000
Priority Class Name:  system-node-critical
Service Account:      neuron-device-plugin
Node:                 ip-10-0-2-86.us-west-2.compute.internal/10.0.2.86
Start Time:           Sat, 12 Sep 2026 18:33:09 +0000
Labels:               app.kubernetes.io/name=neuron-device-plugin
                      controller-revision-hash=6fcd58bb84
                      name=neuron-device-plugin-ds
                      pod-template-generation=1
Annotations:          <none>
Status:               Running
IP:                   10.0.2.89
IPs:
  IP:           10.0.2.89
Controlled By:  DaemonSet/neuron-device-plugin
Containers:
  neuron-device-plugin:
    Container ID:   containerd://da74a9cb5304184d59c0d1e3e5adbf760db90d64e418b29b596ccd54ca005470
    Image:          public.ecr.aws/neuron/neuron-device-plugin:2.23.30.0
    Image ID:       public.ecr.aws/neuron/neuron-device-plugin@sha256:75a6d5ce3bd397c4d05ce7dd4b51a306c7f0a0e1c146710029d5144caed94aa1
    Port:           <none>
    Host Port:      <none>

... 이하 생략
ubuntu@ip-10-0-1-41:~/workshop$ k exec -it -n kube-system ds/neuron-device-plugin -- ls -l /var/lib/kubelet/device-plugins
total 4
srwxr-xr-x. 1 root root   0 Sep 12 18:32 kubelet.sock
-rw-------. 1 root root 145 Sep 12 18:33 kubelet_internal_checkpoint
srwxr-xr-x. 1 root root   0 Sep 12 18:33 neuron-devplugin.sock
srwxr-xr-x. 1 root root   0 Sep 12 18:33 neuroncore-devplugin.sock
ubuntu@ip-10-0-1-41:~/workshop$ k exec -it -n kube-system ds/neuron-device-plugin -- ls -l /opt/aws
total 16
drwxr-xr-x. 3 root root    45 Sep  3 03:18 apitools
drwxr-xr-x. 2 root root 16384 Sep  3 03:18 bin
drwxr-xr-x. 5 root root    41 Sep  3 03:22 neuron
ubuntu@ip-10-0-1-41:~/workshop$ k exec -it -n kube-system ds/neuron-device-plugin -- ls -R -1 /opt/aws/neuron
/opt/aws/neuron:
bin
lib
share

/opt/aws/neuron/bin:
api_pb2.py
api_pb2_grpc.py
default-slurm-setup.sh
nccom-test
neuron-bench
neuron-dbg
neuron-dump
neuron-dump.py
neuron-explorer
neuron-ls
neuron-monitor
neuron-monitor-cloudwatch.py
neuron-monitor-device-view.py
neuron-monitor-k8s-info.py
neuron-monitor-prometheus.py
neuron-monitor-top.py
neuron-profile
neuron-top

/opt/aws/neuron/lib:
libndbg.so

/opt/aws/neuron/share:
man

/opt/aws/neuron/share/man:
man1

/opt/aws/neuron/share/man/man1:
neuron-ls.1
neuron-monitor.
이렇게 하면 새 노드가 잘 떠있는 것을 확인할 수 있습니다.
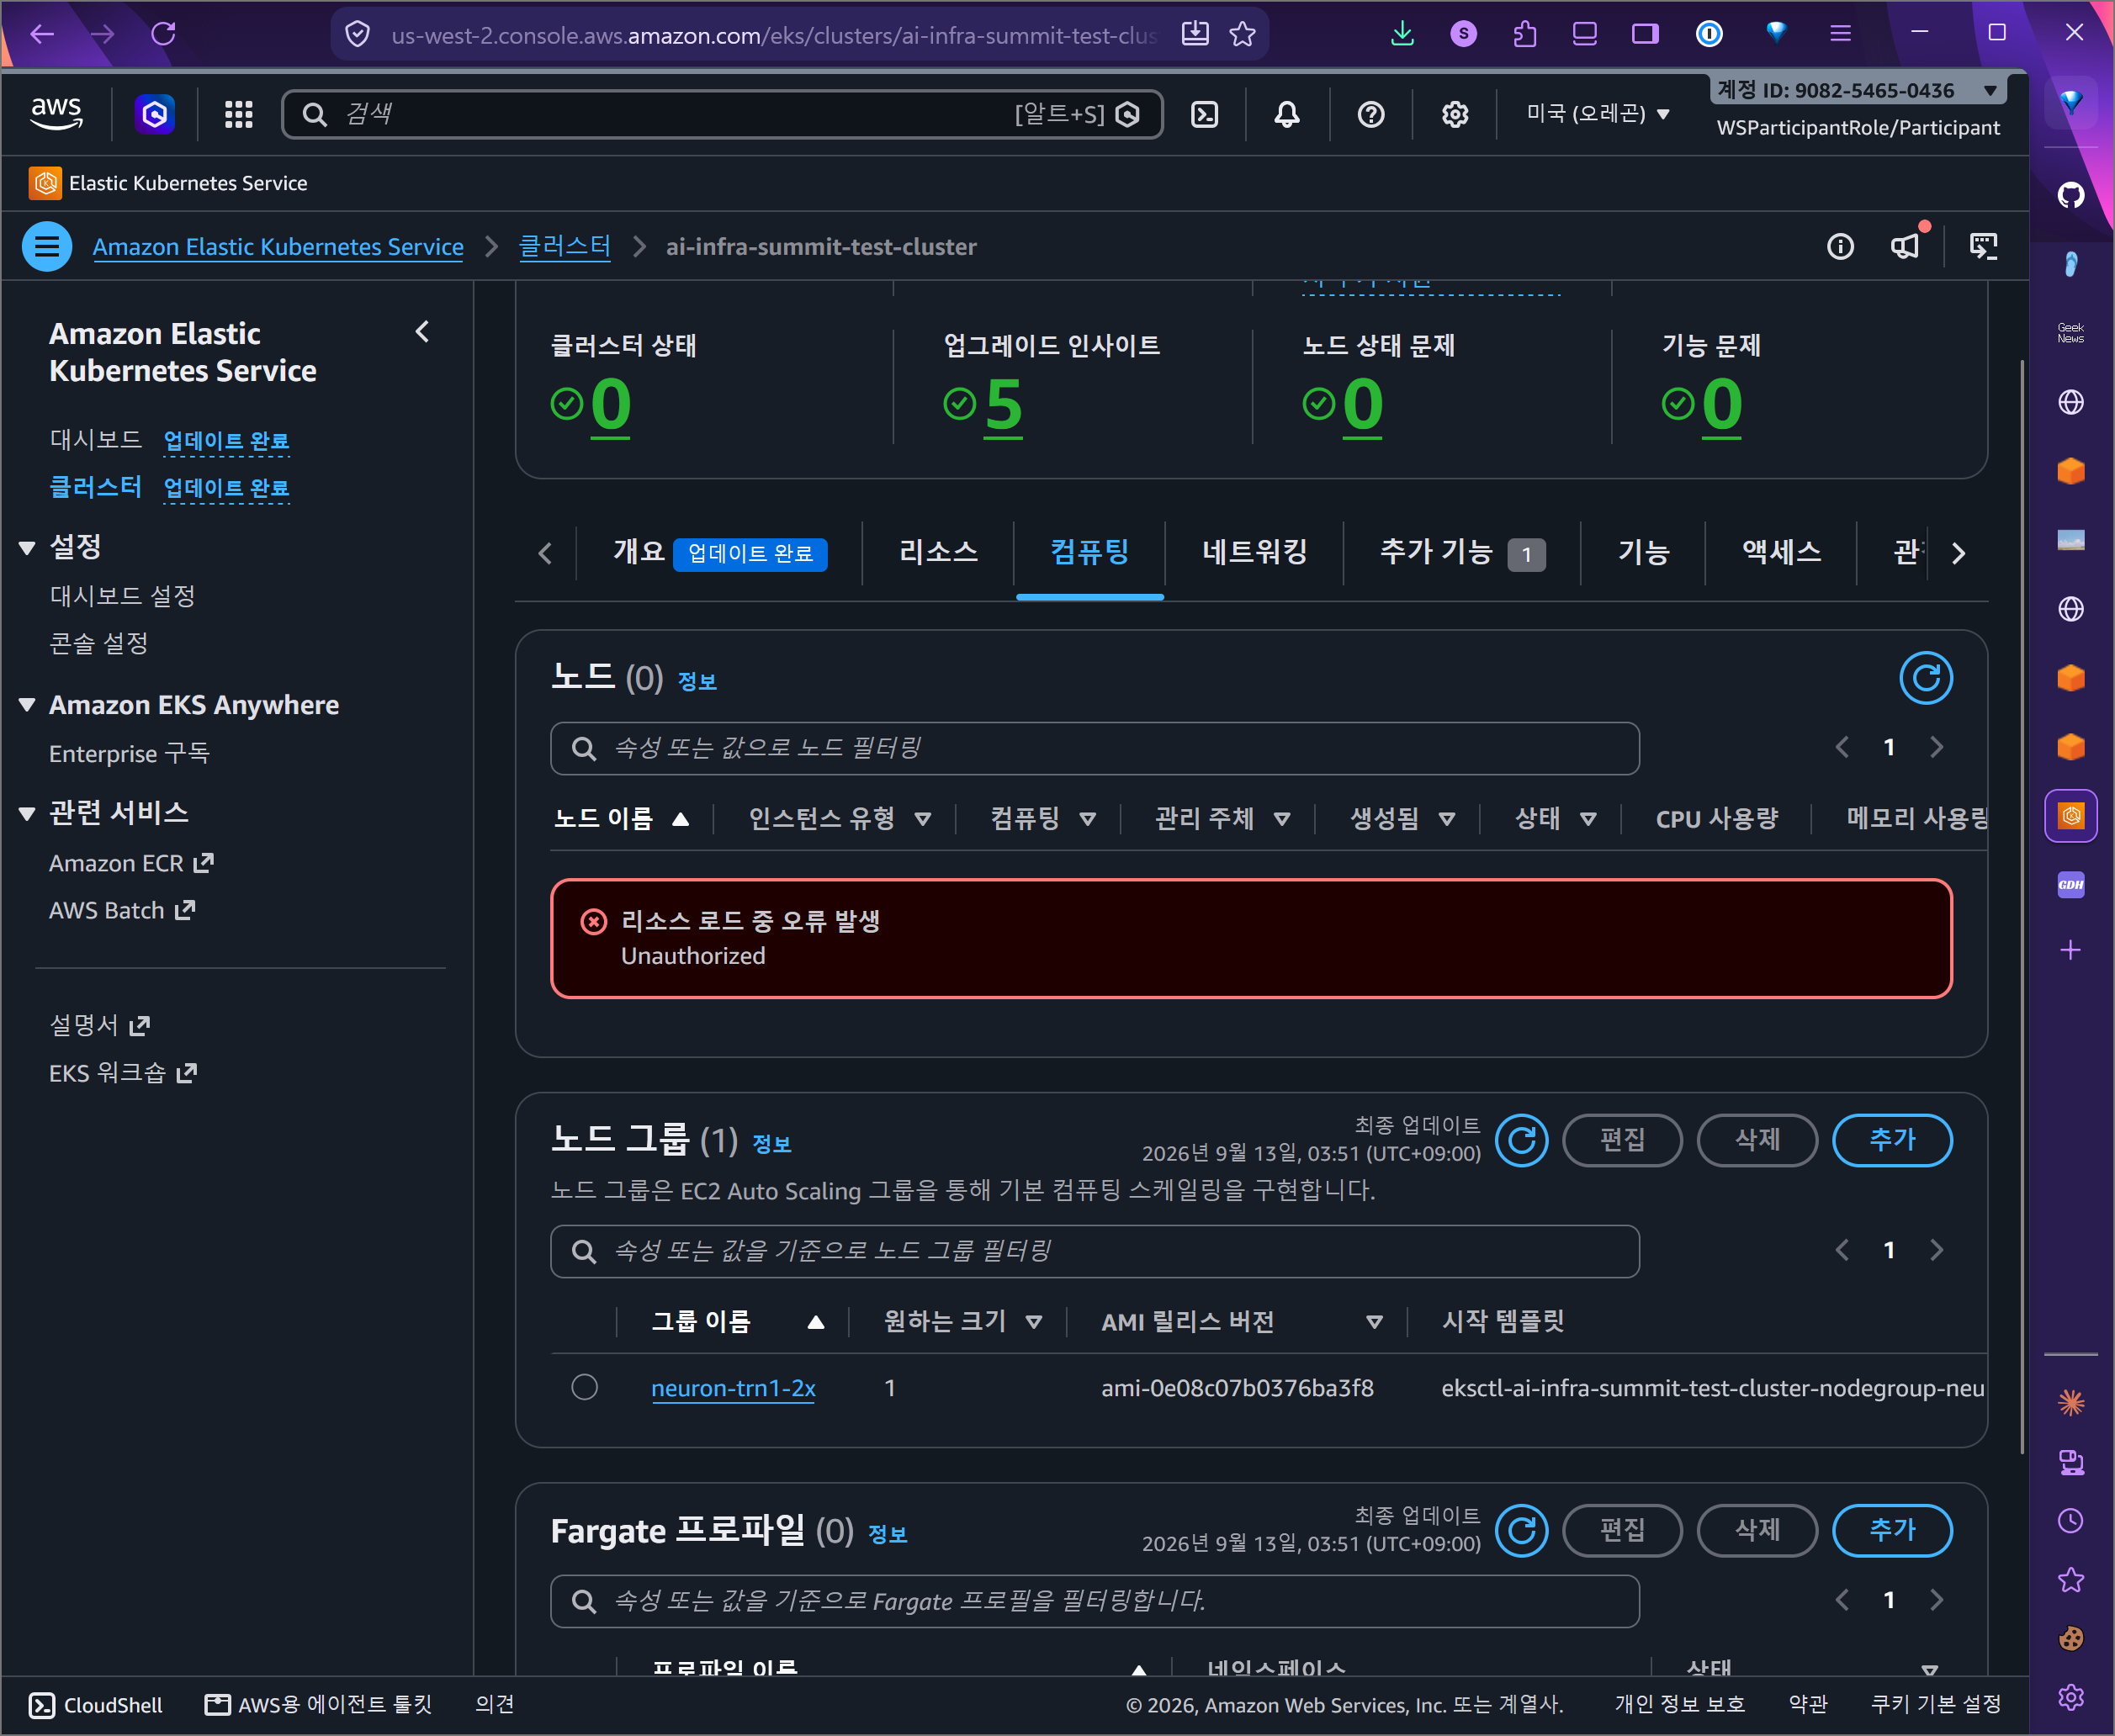
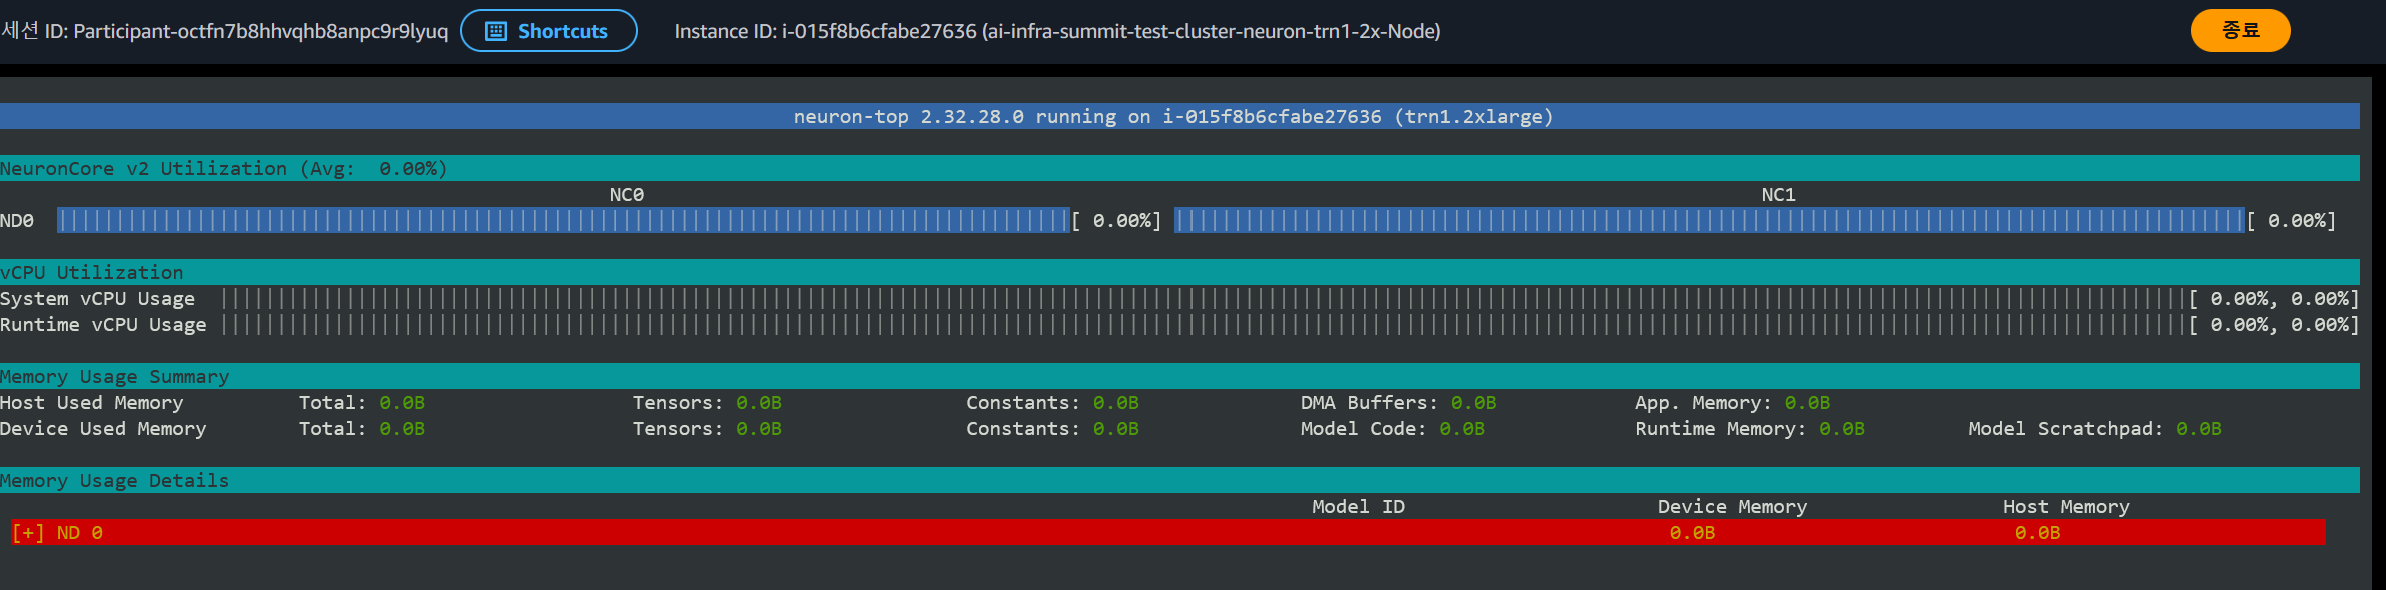
직접 session manager로 들어가서 확인해보죠.
neuron-ls, neuron-top 돌려보기
sh-5.2$ whoami
ssm-user
sh-5.2$ pwd
/usr/bin
sh-5.2$ sudo su ec2-user
[ec2-user@ip-10-0-2-86 bin]$ whoami
ec2-user
[ec2-user@ip-10-0-2-86 bin]$ pwd
/usr/bin
[ec2-user@ip-10-0-2-86 bin]$ cd
[ec2-user@ip-10-0-2-86 ~]$ pwd
/home/ec2-user
[ec2-user@ip-10-0-2-86 ~]$ lspci
00:00.0 Host bridge: Intel Corporation 440FX - 82441FX PMC [Natoma]
00:01.0 ISA bridge: Intel Corporation 82371SB PIIX3 ISA [Natoma/Triton II]
00:01.3 Non-VGA unclassified device: Intel Corporation 82371AB/EB/MB PIIX4 ACPI (rev 08)
00:03.0 VGA compatible controller: Amazon.com, Inc. Device 1111
00:04.0 Non-Volatile memory controller: Amazon.com, Inc. NVMe EBS Controller
00:05.0 Ethernet controller: Amazon.com, Inc. Elastic Network Adapter (ENA)
00:06.0 Ethernet controller: Amazon.com, Inc. Elastic Network Adapter (ENA)
00:1e.0 System peripheral: Amazon.com, Inc. NeuronDevice (Trainium)
00:1f.0 Non-Volatile memory controller: Amazon.com, Inc. NVMe SSD Controller
[ec2-user@ip-10-0-2-86 ~]$ lsmod | grep -i neuron
neuron                491520  2
[ec2-user@ip-10-0-2-86 ~]$ ls -l /dev/neuron0
crw-rw-rw-. 1 root root 243, 0 Sep 12 18:31 /dev/neuron0
[ec2-user@ip-10-0-2-86 ~]$ ls -l /dev/ng*
crw-------. 1 root root 246, 0 Sep 12 18:31 /dev/ng0n1
crw-------. 1 root root 246, 1 Sep 12 18:31 /dev/ng1n1
[ec2-user@ip-10-0-2-86 ~]$ cat /etc/containerd/config.toml
version = 3
root = "/var/lib/containerd"
state = "/run/containerd"

[grpc]
address = "/run/containerd/containerd.sock"

[plugins.'io.containerd.cri.v1.images']
discard_unpacked_layers = true

[plugins.'io.containerd.cri.v1.images'.pinned_images]
sandbox = "localhost/kubernetes/pause:latest"

[plugins."io.containerd.cri.v1.images".registry]
config_path = "/etc/containerd/certs.d:/etc/docker/certs.d"

[plugins.'io.containerd.cri.v1.runtime']
enable_cdi = true

[plugins.'io.containerd.cri.v1.runtime'.containerd]
default_runtime_name = "runc"

[plugins.'io.containerd.cri.v1.runtime'.containerd.runtimes.runc]
runtime_type = "io.containerd.runc.v2"
base_runtime_spec = "/etc/containerd/base-runtime-spec.json"

[plugins.'io.containerd.cri.v1.runtime'.containerd.runtimes.runc.options]
BinaryName = "/usr/sbin/runc"
SystemdCgroup = true

[plugins.'io.containerd.cri.v1.runtime'.cni]
bin_dir = "/opt/cni/bin"
conf_dir = "/etc/cni/net.d"

[ec2-user@ip-10-0-2-86 ~]$ ls -R -1 /opt/aws/neuron/
/opt/aws/neuron/:
bin
lib
share

/opt/aws/neuron/bin:
api_pb2.py
api_pb2_grpc.py
default-slurm-setup.sh
nccom-test
neuron-bench
neuron-dbg
neuron-dump
neuron-dump.py
neuron-explorer
neuron-ls
neuron-monitor
neuron-monitor-cloudwatch.py
neuron-monitor-device-view.py
neuron-monitor-k8s-info.py
neuron-monitor-prometheus.py
neuron-monitor-top.py
neuron-profile
neuron-top

/opt/aws/neuron/lib:
libndbg.so

/opt/aws/neuron/share:
man

/opt/aws/neuron/share/man:
man1

/opt/aws/neuron/share/man/man1:
neuron-ls.1
neuron-monitor.1
[ec2-user@ip-10-0-2-86 ~]$ which neuron-ls
/opt/aws/neuron/bin/neuron-ls
[ec2-user@ip-10-0-2-86 ~]$ neuron-ls
instance-type: trn1.2xlarge
instance-id: i-015f8b6cfabe27636
+--------+--------+----------+--------+--------------+----------+------+
| NEURON | NEURON |  NEURON  | NEURON |     PCI      |   CPU    | NUMA |
| DEVICE | CORES  | CORE IDS | MEMORY |     BDF      | AFFINITY | NODE |
+--------+--------+----------+--------+--------------+----------+------+
| 0      | 2      | 0-1      | 32 GB  | 0000:00:1e.0 | 0-7      | -1   |
+--------+--------+----------+--------+--------------+----------+------+
neuron cache용 버킷 생성
neuron-cache 를 담을 버킷을 생성합니다.
ubuntu@ip-10-0-1-41:~/workshop$ echo $BUCKET_NAME
ai-infra-summit-vllm-models-cache-908254650436
ubuntu@ip-10-0-1-41:~/workshop$ aws s3 mb "s3://$BUCKET_NAME" --region "$AWS_REGION"
make_bucket: ai-infra-summit-vllm-models-cache-908254650436
ubuntu@ip-10-0-1-41:~/workshop$ aws s3 ls
2026-09-12 18:58:30 ai-infra-summit-vllm-models-cache-908254650436
neuron device plugin 재설치
neuron device plugin을 재설치하고 neuron 스케줄러 확장을 설치합니다.
neuron-device-plugin과 향후 Helm으로 설치할 플러그인이 충돌하기 때문입니다.
사전에 설치한 리소스는 Helm으로 관리되지 않아서 k8s의 관리하에 들어오지 않아 이를 싱크맞추기 위함입니다.
그러므로 싹 지우고,
# Clean Up Any Existing Neuron Components
k delete daemonset neuron-device-plugin -n kube-system
k delete clusterrole neuron-device-plugin
k delete serviceaccount neuron-device-plugin -n kube-system
k delete clusterrolebinding neuron-device-plugin

daemonset.apps "neuron-device-plugin" deleted from kube-system namespace
clusterrole.rbac.authorization.k8s.io "neuron-device-plugin" deleted
serviceaccount "neuron-device-plugin" deleted from kube-system namespace
clusterrolebinding.rbac.authorization.k8s.io "neuron-device-plugin" deleted
Helm으로 아무것도 없는걸 확인하고, 마저 설치합시다.
ubuntu@ip-10-0-1-41:~/workshop$ helm list -A
NAME    NAMESPACE       REVISION        UPDATED STATUS  CHART   APP VERSION

ubuntu@ip-10-0-1-41:~/workshop$ helm upgrade --install neuron-helm-chart oci://public.ecr.aws/neuron/neuron-helm-chart --set "npd.enabled=false"
Release "neuron-helm-chart" does not exist. Installing it now.
Pulled: public.ecr.aws/neuron/neuron-helm-chart:1.10.0
Digest: sha256:ed5d8f73b7a05d3a1edf17b2bfaf277ea995ad1c65b115fa8ba2c7b4dc649346
NAME: neuron-helm-chart
LAST DEPLOYED: Sat Sep 12 19:04:18 2026
NAMESPACE: default
STATUS: deployed
REVISION: 1
NOTES:

ubuntu@ip-10-0-1-41:~/workshop$ helm list -A
NAME                    NAMESPACE       REVISION        UPDATED                                 STATUS          CHART                     APP VERSION
neuron-helm-chart       default         1               2026-09-12 19:04:18.94730929 +0000 UTC  deployed        neuron-helm-chart-1.10.0  1.10.0
새로뜬걸 확인하고, neuron core와 디바이스가 잘 할당되었나 봅시다.
ubuntu@ip-10-0-1-41:~/workshop$ k get ds neuron-device-plugin -n kube-system
NAME                   DESIRED   CURRENT   READY   UP-TO-DATE   AVAILABLE   NODE SELECTOR   AGE
neuron-device-plugin   1         1         1       1            1           <none>          65s

ubuntu@ip-10-0-1-41:~/workshop$ k get nodes "-o=custom-columns=NAME:.metadata.name,NeuronCore:.status.allocatable.aws\.amazon\.com/neuroncore"
NAME                                      NeuronCore
ip-10-0-2-86.us-west-2.compute.internal   2
이후 neuron-scheduler-extension을 설치합시다.
ubuntu@ip-10-0-1-41:~/workshop$ helm upgrade --install neuron-helm-chart oci://public.ecr.aws/neuron/neuron-helm-chart \
    --set "scheduler.enabled=true" \
    --set "npd.enabled=false"
Pulled: public.ecr.aws/neuron/neuron-helm-chart:1.10.0
Digest: sha256:ed5d8f73b7a05d3a1edf17b2bfaf277ea995ad1c65b115fa8ba2c7b4dc649346
Release "neuron-helm-chart" has been upgraded. Happy Helming!
NAME: neuron-helm-chart
LAST DEPLOYED: Sat Sep 12 19:06:38 2026
NAMESPACE: default
STATUS: deployed
REVISION: 2
NOTES:
잘 떠있는지 확인해볼까요.
ubuntu@ip-10-0-1-41:~/workshop$ k get pod -n kube-system -l app.kubernetes.io/component=k8s-neuron-scheduler
k get deploy -n kube-system k8s-neuron-scheduler

NAME                                    READY   STATUS    RESTARTS   AGE
k8s-neuron-scheduler-785c8d99f8-n2lt8   1/1     Running   0          27s
NAME                   READY   UP-TO-DATE   AVAILABLE   AGE
k8s-neuron-scheduler   1/1     1            1           28s


ubuntu@ip-10-0-1-41:~/workshop$ k get pod -n kube-system -l app.kubernetes.io/component=my-scheduler
k get deploy -n kube-system my-scheduler
NAME                            READY   STATUS    RESTARTS   AGE
my-scheduler-55f56bc9f8-8k42m   1/1     Running   0          61s
NAME           READY   UP-TO-DATE   AVAILABLE   AGE
my-scheduler   1/1     1            1           62s
Amazon S3 CSI 드라이버 설치하기
쿠버네티스에서 S3에 붙을 수 있도록 CSI 드라이버를 설치합시다.
ubuntu@ip-10-0-1-41:~/workshop$ helm repo add aws-mountpoint-s3-csi-driver https://awslabs.github.io/mountpoint-s3-csi-driver
"aws-mountpoint-s3-csi-driver" has been added to your repositories
ubuntu@ip-10-0-1-41:~/workshop$ helm repo update
Hang tight while we grab the latest from your chart repositories...
...Successfully got an update from the "aws-mountpoint-s3-csi-driver" chart repository
Update Complete. ⎈Happy Helming!⎈
ubuntu@ip-10-0-1-41:~/workshop$ helm upgrade --install aws-mountpoint-s3-csi-driver \
    --namespace kube-system \
    aws-mountpoint-s3-csi-driver/aws-mountpoint-s3-csi-driver
Release "aws-mountpoint-s3-csi-driver" does not exist. Installing it now.
NAME: aws-mountpoint-s3-csi-driver
LAST DEPLOYED: Sat Sep 12 19:08:42 2026
NAMESPACE: kube-system
STATUS: deployed
REVISION: 1
TEST SUITE: None
NOTES:
Thank you for using Mountpoint for Amazon S3 CSI Driver v2.8.0.

Learn more about the file system operations Mountpoint supports: https://github.com/awslabs/mountpoint-s3/blob/main/doc/SEMANTICS.md
잘 떠있군요!
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get pods -n kube-system -l app.kubernetes.io/name=aws-mountpoint-s3-csi-driver
NAME                                 READY   STATUS    RESTARTS   AGE
s3-csi-controller-5df587766f-s8vz2   1/1     Running   0          21s
s3-csi-node-gnjmm                    3/3     Running   0          21s
클러스터가 잘 살아있나 살펴봅시다.
ubuntu@ip-10-0-1-41:~/workshop$ echo "=== Cluster Status ==="
kubectl get nodes

echo -e "\n=== Neuron Devices ==="
kubectl describe nodes -l alpha.eksctl.io/nodegroup-name=neuron-trn1-2x | grep "aws.amazon.com/neuron"

echo -e "\n=== Storage Classes ==="
kubectl get storageclass

echo -e "\n=== Current Namespace ==="
kubectl config get-contexts
=== Cluster Status ===
NAME                                      STATUS   ROLES    AGE   VERSION
ip-10-0-2-86.us-west-2.compute.internal   Ready    <none>   41m   v1.33.13-eks-cb19647

=== Neuron Devices ===
  aws.amazon.com/neuron:      1
  aws.amazon.com/neuroncore:  2
  aws.amazon.com/neuron:      1
  aws.amazon.com/neuroncore:  2
  aws.amazon.com/neuron      0           0
  aws.amazon.com/neuroncore  0           0

=== Storage Classes ===
NAME   PROVISIONER             RECLAIMPOLICY   VOLUMEBINDINGMODE      ALLOWVOLUMEEXPANSION   AGE
gp2    kubernetes.io/aws-ebs   Delete          WaitForFirstConsumer   false                  38h

=== Current Namespace ===
CURRENT   NAME                                                                      CLUSTER                   AUTHINFO                                                                  NAMESPACE
*         arn:aws:eks:us-west-2:REDACTED:cluster/ai-infra-summit-test-cluster   arn:aws:eks:us-west-2:REDACTED:cluster/ai-infra-summit-test-cluster   arn:aws:eks:us-west-2:REDACTED:cluster/ai-infra-summit-test-cluster
지금까지 아래 내용을 구성했습니다.
- EKS 클러스터
- Neuron 관리형 노드그룹
- Neuron 디바이스 플러그인(재설치)
- S3 모델 캐시
- IAM 권한 관리
추가: NVIDIA GPU 리소스 vs Neuron GPU 리소스
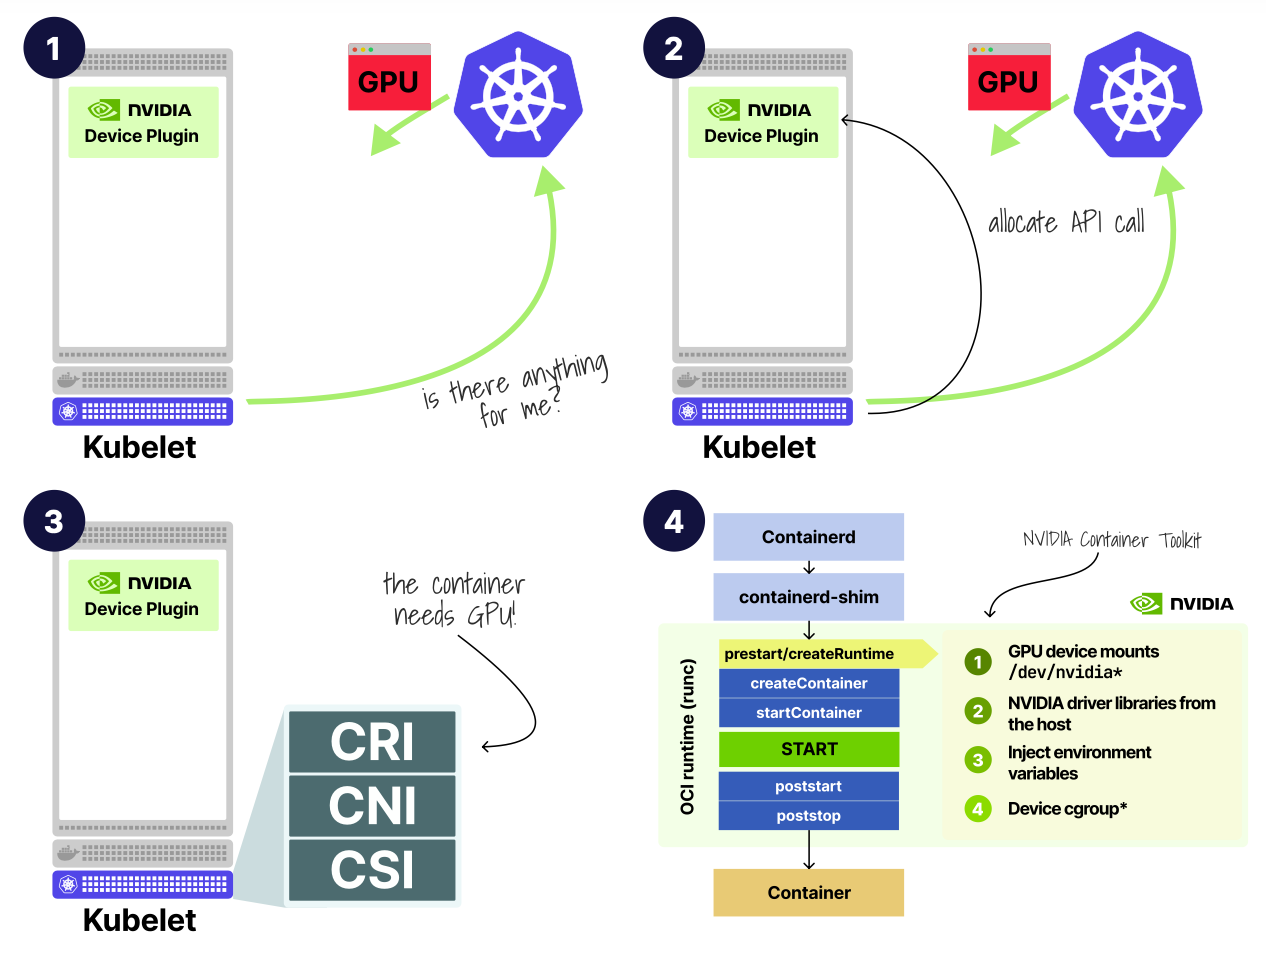
보통은 그럼 컨테이너/파드가 NVIDIA GPU를 쓸텐데, 이럼 Neuron GPU 리소스와는 어떤 차이가 있을까요?
NVIDIA 설정
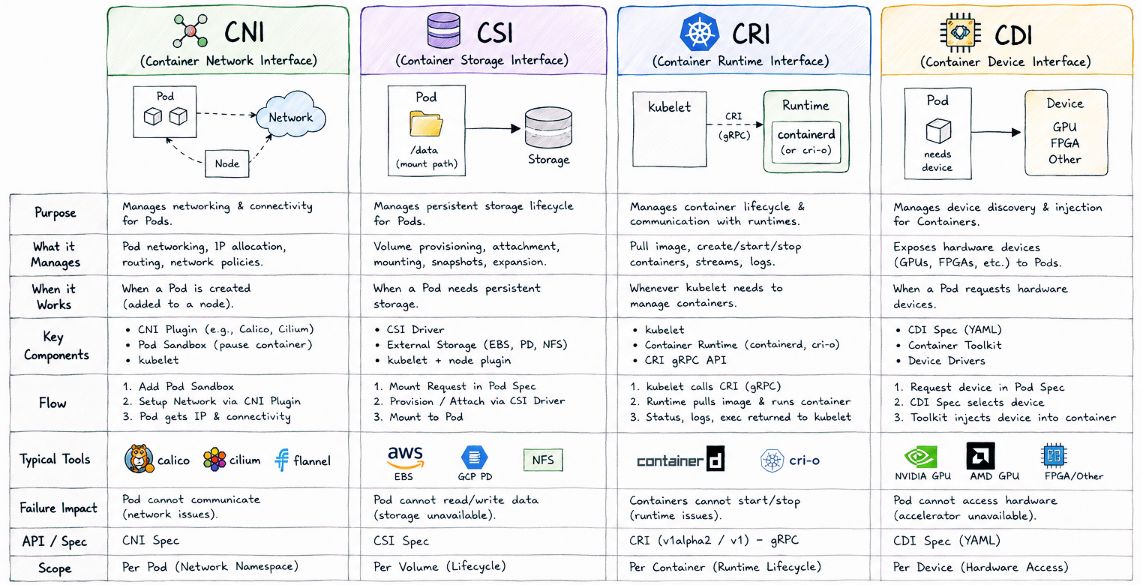
Neuron 설정
통상의 엔비디아 GPU 리소스 활용의 경우 컨테이너 런타임이 시스템 깊숙하게 관여해야하기 때문이고, Neuron GPU 리소스는 커널레벨, 유저영역의 SDK 관리를 해두었기 때문에 가능합니다. Neuron GPU의 세밀한 제어는 전용 커스텀 스케줄러 확장이 필요합니다.
Lab 2: vLLM 배포
여기서는 초기화 컨테이너 패턴을 쓰는 파드를 통해 EKS 클러스터에 vLLM을 배포해볼 예정입니다.
허깅페이스 토큰 관리용 시크릿 생성
학습을 위해 Write 토큰을 만들고, 본 스터디가 종료되면 바로 삭제하시면 됩니다.
ubuntu@ip-10-0-1-41:~/workshop$ rm -rf .env
ubuntu@ip-10-0-1-41:~/workshop$ echo 'HF_TOKEN="hf_<REDACTED>"' > ~/workshop/.env
ubuntu@ip-10-0-1-41:~/workshop$ source /home/ubuntu/workshop/.env
ubuntu@ip-10-0-1-41:~/workshop$ echo $HF_TOKEN
hf_<REDACTED>
ubuntu@ip-10-0-1-41:~/workshop$ k create secret generic hf-token-secret \
    --from-literal=HF_TOKEN="$HF_TOKEN" \
    --dry-run=client -o yaml | kubectl apply -f -
secret/hf-token-secret created
ubuntu@ip-10-0-1-41:~/workshop$ k get secret hf-token-secret
NAME              TYPE     DATA   AGE
hf-token-secret   Opaque   1      8s
vLLM 배포에 필요한 env 저장용 ConfigMap 생성
아래 내용의 ConfigMap 을 만들고 즉시 배포합니다.
vllm-configmap.yaml 파일
apiVersion: v1
kind: ConfigMap
metadata:
  name: vllm-shared-config
data:
  HF_TOKEN: "hf_<REDACTED>"
  MODEL_NAME: "tinyLlama/TinyLlama-1.1B-Chat-v1.0"  # 서빙할 대상 모델 (경량 1.1B 모델이라 트레이닝/컴파일이 빠름)
  S3_BUCKET: "ai-infra-summit-vllm-models-cache-<REDACTED>" # 컴파일된 Neuron 아티팩트를 캐싱할 S3 버킷
  S3_PREFIX: "compiled-models"                      # 캐시 오브젝트를 저장할 prefix 경로
  MAX_NUM_SEQS: "4"                                 # vLLM continuous batching이 동시에 처리할 최대 시퀀스(요청) 수 — 배치 크기 상한
  PORT: "8080"
  NEURON_COMPILED_ARTIFACTS: "/shared/model/cache"  # Neuron 컴파일러(neuronx-cc)가 컴파일 결과를 읽고 쓰는 로컬 경로 — S3 PVC가 마운트되는 지점과 동일
  NEURON_COMPILE_CACHE_URL: "/shared/model/cache"   # 상동
  TENSOR_PARALLEL_SIZE: "2"                         # 모델 가중치를 2개 NeuronCore에 분할(텐서 병렬) — trn1.2xlarge 칩 1개의 코어 2개 전부 사용
  MAX_MODEL_LEN: "1024"                             # 시퀀스(프롬프트+생성) 최대 토큰 길이, KV 캐시 크기 산정 기준
  NEURON_RT_VISIBLE_CORES: "0-1"                    # Neuron 런타임에 노출할 코어 인덱스 범위 — 코어 0,1 두 개 다 이 프로세스 전용으로 지정
  NEURON_RT_LOG_LEVEL: "ERROR"                      # Neuron 런타임 로그 레벨 — 에러만 출력해 노이즈 최소화
  NEURON_RT_ASYNC_EXEC_MAX_INFLIGHT_REQUESTS: "4"   # Neuron 런타임에 동시에 비동기로 in-flight될 수 있는 실행 요청 수 상한 (throughput/latency 트레이드오프 튜닝값)
  VLLM_NEURON_FRAMEWORK: "neuronx-distributed-inference" # vLLM이 Neuron 백엔드로 NxD(NeuronX Distributed) 추론 프레임워크를 사용하도록 지정하는 플래그
배포 완료를 확인합니다.
configmap/vllm-shared-config created
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get cm vllm-shared-config
NAME                 DATA   AGE
vllm-shared-config   14     49s
모델 아티팩트 캐싱용 PV, PVC(s3 기반) 배포
마찬가지로 즉시 배포하고 확인합니다.
vllm-storage.yaml 파일
apiVersion: v1
kind: ConfigMap
metadata:
  name: vllm-shared-config
data:
  HF_TOKEN: "hf_<REDACTED>"
  MODEL_NAME: "tinyLlama/TinyLlama-1.1B-Chat-v1.0"  # 서빙할 대상 모델 (경량 1.1B 모델이라 트레이닝/컴파일이 빠름)
  S3_BUCKET: "ai-infra-summit-vllm-models-cache-<REDACTED>" # 컴파일된 Neuron 아티팩트를 캐싱할 S3 버킷
  S3_PREFIX: "compiled-models"                      # 캐시 오브젝트를 저장할 prefix 경로
  MAX_NUM_SEQS: "4"                                 # vLLM continuous batching이 동시에 처리할 최대 시퀀스(요청) 수 — 배치 크기 상한
  PORT: "8080"
  NEURON_COMPILED_ARTIFACTS: "/shared/model/cache"  # Neuron 컴파일러(neuronx-cc)가 컴파일 결과를 읽고 쓰는 로컬 경로 — S3 PVC가 마운트되는 지점과 동일
  NEURON_COMPILE_CACHE_URL: "/shared/model/cache"   # 상동
  TENSOR_PARALLEL_SIZE: "2"                         # 모델 가중치를 2개 NeuronCore에 분할(텐서 병렬) — trn1.2xlarge 칩 1개의 코어 2개 전부 사용
  MAX_MODEL_LEN: "1024"                             # 시퀀스(프롬프트+생성) 최대 토큰 길이, KV 캐시 크기 산정 기준
  NEURON_RT_VISIBLE_CORES: "0-1"                    # Neuron 런타임에 노출할 코어 인덱스 범위 — 코어 0,1 두 개 다 이 프로세스 전용으로 지정
  NEURON_RT_LOG_LEVEL: "ERROR"                      # Neuron 런타임 로그 레벨 — 에러만 출력해 노이즈 최소화
  NEURON_RT_ASYNC_EXEC_MAX_INFLIGHT_REQUESTS: "4"   # Neuron 런타임에 동시에 비동기로 in-flight될 수 있는 실행 요청 수 상한 (throughput/latency 트레이드오프 튜닝값)
  VLLM_NEURON_FRAMEWORK: "neuronx-distributed-inference" # vLLM이 Neuron 백엔드로 NxD(NeuronX Distributed) 추론 프레임워크를 사용하도록 지정하는 플래그
persistentvolume/s3-model-cache-pv created
persistentvolumeclaim/s3-model-cache-pvc created
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get pvc,pv
NAME                                       STATUS   VOLUME              CAPACITY   ACCESS MODES   STORAGECLASS   VOLUMEATTRIBUTESCLASS   AGE
persistentvolumeclaim/s3-model-cache-pvc   Bound    s3-model-cache-pv   100Gi      RWX                           <unset>                 2m48s

NAME                                 CAPACITY   ACCESS MODES   RECLAIM POLICY   STATUS   CLAIM                        STORAGECLASS   VOLUMEATTRIBUTESCLASS   REASON   AGE
persistentvolume/s3-model-cache-pv   100Gi      RWX            Retain           Bound    default/s3-model-cache-pvc                  <unset>                          2m48s
vLLM deployment 배포
초기화 컨테이너와 vLLM 서버 컨테이너로 분리합니다.
- 초기화 컨테이너의 역할
- S3 캐시 확인
- (없다면) 허깅페이스에서 다운로드
- Neuron용 컴파일
- S3에 캐시 업로드
- vLLM 서버 컨테이너
- 추론 API 서빙
- OpenAI 호환 REST API 엔드포인트 서빙
- 요청을 효율적으로 관리하도록 설계
노드 설정을 한번 더 확인하고,
ubuntu@ip-10-0-1-41:~/workshop$ k describe node
Name:               ip-10-0-2-86.us-west-2.compute.internal
Roles:              <none>
Labels:             alpha.eksctl.io/cluster-name=ai-infra-summit-test-cluster
                    alpha.eksctl.io/nodegroup-name=neuron-trn1-2x
바로 배포합시다. 뜨기까지 조금 오래걸립니다! (체감상 10분 이내)
vLLM 버전과 기타 버전은 고정이 필요합니다!
vLLM은 버전업 시 굉장히 많은 것이 빠르게 바뀌기 때문에 버전업으로 문제가 발생할 수 있다는 점을 염두에 둬주세요.
vllm-deployment.yaml 파일
apiVersion: apps/v1
kind: Deployment
metadata:
  name: vllm-deployment
  labels:
    app.kubernetes.io/name: vllm-server
spec:
  replicas: 1
  selector:
    matchLabels:
      app.kubernetes.io/name: vllm-server
  template:
    metadata:
      labels:
        app.kubernetes.io/name: vllm-server
    spec:
      restartPolicy: Always
      schedulerName: my-scheduler
      nodeSelector:
        alpha.eksctl.io/nodegroup-name: neuron-trn1-2x
      tolerations:
        - key: "node.kubernetes.io/disk-pressure"
          operator: "Exists"
          effect: "NoSchedule"
      # Volumes for compiled models
      volumes:
        - name: model-storage
          persistentVolumeClaim:
            claimName: s3-model-cache-pvc
      # Init container that downloads, compiles, and uploads model to S3
      initContainers:
        - name: model-prep
          image: public.ecr.aws/neuron/pytorch-inference-vllm-neuronx:0.9.1-neuronx-py310-sdk2.25.0-ubuntu22.04
          imagePullPolicy: Always
          envFrom:
            - configMapRef:
                name: vllm-shared-config
            - secretRef:
                name: hf-token-secret
          command: ["/bin/bash", "-c"]
          args:
            - |
              set -e
              echo "Starting model prep for $MODEL_NAME..."
              huggingface-cli login --token "$HF_TOKEN"
              mkdir -p /tmp/cache /shared/model/cache

              if [ ! "$(ls -A /shared/model/cache 2>/dev/null)" ]; then
                export NEURON_COMPILED_ARTIFACTS=/tmp/cache NEURON_COMPILE_CACHE_URL=/tmp/cache
                python3 -c "
              import os
              from vllm import LLM
              LLM(model=os.environ['MODEL_NAME'], max_num_seqs=int(os.environ['MAX_NUM_SEQS']),
                  max_model_len=int(os.environ['MAX_MODEL_LEN']), tensor_parallel_size=int(os.environ['TENSOR_PARALLEL_SIZE']),
                  device='neuron', override_neuron_config={'enable_bucketing': False})
              print('Model compiled successfully!')"
                cp -r /tmp/cache/* /shared/model/cache/ 2>/dev/null || true
              else
                echo "Model cache exists, skipping compilation"
              fi
          resources:
            limits:
              aws.amazon.com/neuron: 1
              ephemeral-storage: 50Gi
            requests:
              aws.amazon.com/neuron: 1
              ephemeral-storage: 50Gi
          volumeMounts:
            - name: model-storage
              mountPath: /shared/model
      containers:
        - name: vllm-server
          image: public.ecr.aws/neuron/pytorch-inference-vllm-neuronx:0.9.1-neuronx-py310-sdk2.25.0-ubuntu22.04
          imagePullPolicy: Always
          ports:
            - containerPort: 8080
              name: http-vllm
          envFrom:
            - configMapRef:
                name: vllm-shared-config
            - secretRef:
                name: hf-token-secret
          command: ["/bin/bash", "-c"]
          args:
            - |
              python -m vllm.entrypoints.openai.api_server \
                --model="$MODEL_NAME" \
                --max-num-seqs=$MAX_NUM_SEQS \
                --max-model-len=$MAX_MODEL_LEN \
                --tensor-parallel-size=$TENSOR_PARALLEL_SIZE \
                --port=$PORT \
                --device=neuron \
                --override-neuron-config='{"enable_bucketing":false}'
          volumeMounts:
            - name: model-storage
              mountPath: /shared/model
              readOnly: true
          resources:
            limits:
              aws.amazon.com/neuron: 1
              ephemeral-storage: 50Gi
              cpu: "8000m"
            requests:
              aws.amazon.com/neuron: 1
              ephemeral-storage: 50Gi
              cpu: "4000m"
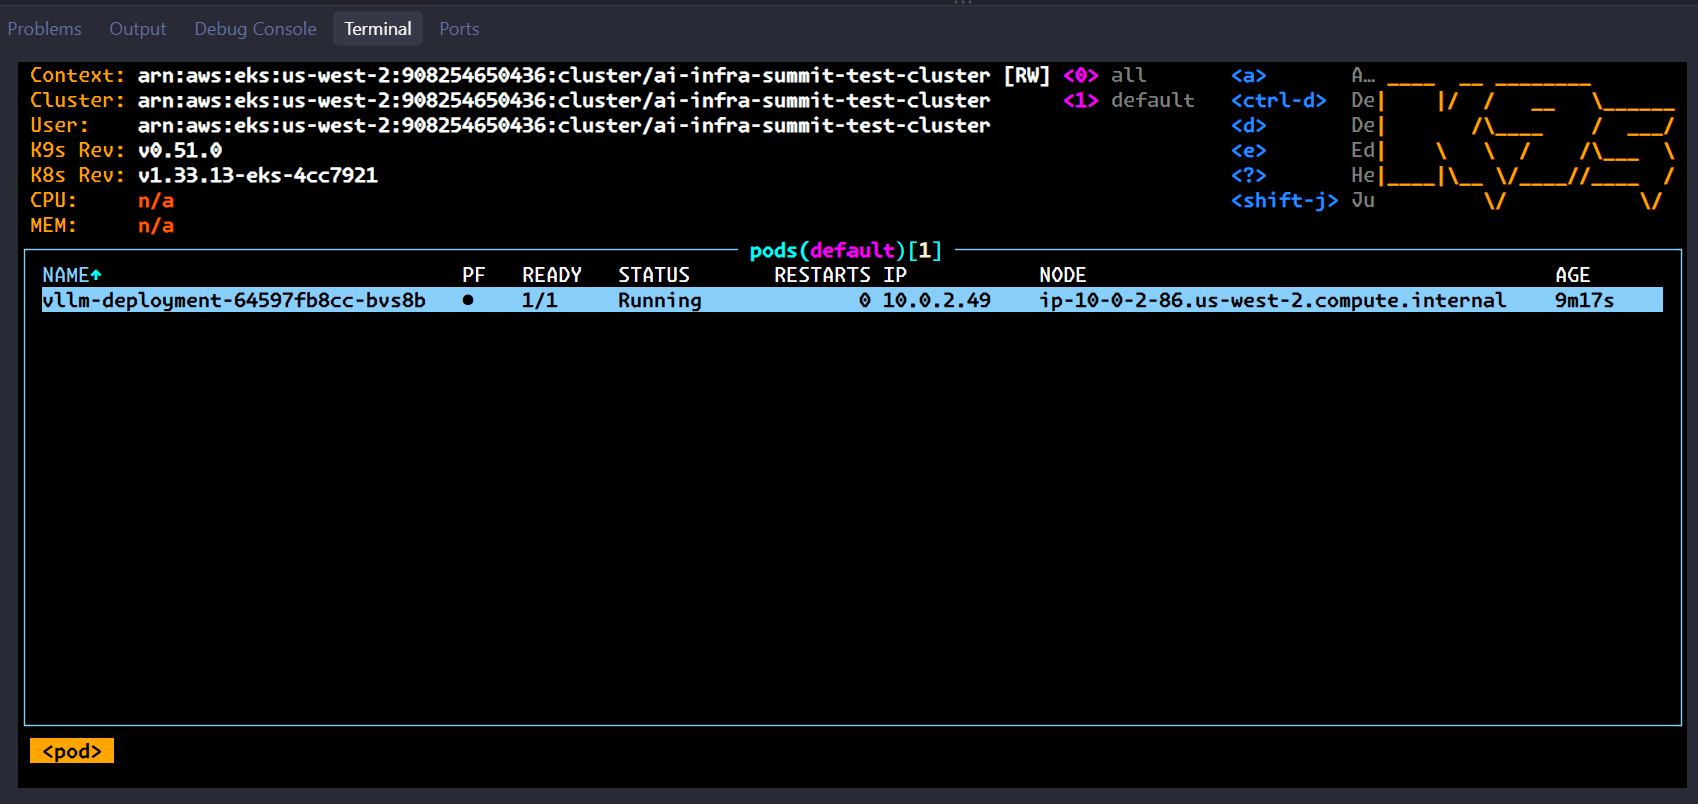
k9s 에도 올라옵니다.
아까전 s3 watch 로 보던 로그에도 캐시 데이터가 올라오고,
2026-09-12 19:49:21    4.6 MiB cache/model.pt
2026-09-12 19:49:21    6.1 KiB cache/neuron_config.json
2026-09-12 19:49:21  359 Bytes cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939/compile_flags.json
2026-09-12 19:49:22    0 Bytes cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939/model.done
2026-09-12 19:49:21  547.2 KiB cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939/model.hlo_module.pb
2026-09-12 19:49:22    1.5 MiB cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939/model.neff
2026-09-12 19:49:22    1.6 MiB cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939/wrapped_neff.hlo
2026-09-12 19:49:22  359 Bytes cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_ae92d68443828ba4e463+ad9e832d/compile_flags.json
2026-09-12 19:49:23    0 Bytes cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_ae92d68443828ba4e463+ad9e832d/model.done
2026-09-12 19:49:22  851.5 KiB cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_ae92d68443828ba4e463+ad9e832d/model.hlo_module.pb
2026-09-12 19:49:23  741.0 KiB cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_ae92d68443828ba4e463+ad9e832d/model.neff
스케줄러는 위에서 재설치한 요소로 반영되었음을 확인할 수 있습니다.
ubuntu@ip-10-0-1-41:~/workshop$ k get pod -l app.kubernetes.io/name=vllm-server -owide
NAME                               READY   STATUS    RESTARTS   AGE   IP          NODE                                      NOMINATED NODE  READINESS GATES
vllm-deployment-64597fb8cc-bvs8b   1/1     Running   0          10m   10.0.2.49   ip-10-0-2-86.us-west-2.compute.internal   <none>  <none>
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get pod -l app.kubernetes.io/name=vllm-server -o yaml | grep -i scheduler
    schedulerName: my-scheduler
vllm-server 파드 내의 정보도 확인해봅시다.
ubuntu@ip-10-0-1-41:~/workshop$ kubectl exec -it deploy/vllm-deployment -c vllm-server -- ls -R -1 /shared/model
/shared/model:
cache

/shared/model/cache:
model.pt
neuron_config.json
neuronxcc-2.20.9961.0+0acef03a

/shared/model/cache/neuronxcc-2.20.9961.0+0acef03a:
MODULE_56f0d314fda2b6e1e336+617f6939
MODULE_ae92d68443828ba4e463+ad9e832d

/shared/model/cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_56f0d314fda2b6e1e336+617f6939:
compile_flags.json
model.done
model.hlo_module.pb
model.neff
wrapped_neff.hlo

/shared/model/cache/neuronxcc-2.20.9961.0+0acef03a/MODULE_ae92d68443828ba4e463+ad9e832d:
compile_flags.json
model.done
model.hlo_module.pb
model.neff
ubuntu@ip-10-0-1-41:~/workshop$ kubectl exec -it deploy/vllm-deployment -c vllm-server -- env | grep -E 'NEURON|VLLM|MAX|TENSOR'
VLLM_TARGET_DEVICE=neuron
NEURON_LOGICAL_NC_CONFIG=1
NEURON_COMPILE_CACHE_URL=/shared/model/cache
TENSOR_PARALLEL_SIZE=2
NEURON_RT_LOG_LEVEL=ERROR
NEURON_RT_VISIBLE_CORES=0-1
VLLM_NEURON_FRAMEWORK=neuronx-distributed-inference
MAX_MODEL_LEN=1024
MAX_NUM_SEQS=4
NEURON_COMPILED_ARTIFACTS=/shared/model/cache
NEURON_RT_ASYNC_EXEC_MAX_INFLIGHT_REQUESTS=4
워커노드에서 확인
로컬 컨테이너 이미지와 vLLM 프로세스, 그리고 S3 마운트를 확인합니다.
[ec2-user@ip-10-0-2-86 ~]$ sudo ctr -n k8s.io images ls | grep -i vllm
WARN[0000] DEPRECATION: The `bin_dir` property of `[plugins."io.containerd.cri.v1.runtime".cni`] is deprecated since containerd v2.1 and will be removed in containerd v2.3. Use `bin_dirs` in the same section instead.
public.ecr.aws/neuron/pytorch-inference-vllm-neuronx:0.9.1-neuronx-py310-sdk2.25.0-ubuntu22.04                                                       application/vnd.docker.distribution.manifest.v2+json      sha256:01f0f7b1e2cf256019a80c16712e79a5f254b04a3a77dbf8ac196de4ee380928 7.9 GiB   linux/amd64                           io.cri-containerd.image=managed
public.ecr.aws/neuron/pytorch-inference-vllm-neuronx@sha256:01f0f7b1e2cf256019a80c16712e79a5f254b04a3a77dbf8ac196de4ee380928                         application/vnd.docker.distribution.manifest.v2+json      sha256:01f0f7b1e2cf256019a80c16712e79a5f254b04a3a77dbf8ac196de4ee380928 7.9 GiB   linux/amd64                           io.cri-containerd.image=managed
[ec2-user@ip-10-0-2-86 ~]$ ps -ef |grep -i vllm
ec2-user   28665   28644  0 19:43 ?        00:00:00 /mountpoint-s3/bin/mount-s3 ai-infra-summit-vllm-models-cache-908254650436 /dev/fd/3 --allow-root --foreground --user-agent-prefix=s3-csi-driver/2.8.0 credential-source#driver k8s/v1.33.13-eks-4cc7921 md/install#helm
root       31365   28797  1 19:49 ?        00:00:08 python -m vllm.entrypoints.openai.api_server --model=tinyLlama/TinyLlama-1.1B-Chat-v1.0 --max-num-seqs=4 --max-model-len=1024 --tensor-parallel-size=2 --port=8080 --device=neuron --override-neuron-config={"enable_bucketing":false}
ec2-user   34320   11700  0 19:57 pts/3    00:00:00 grep --color=auto -i vllm
[ec2-user@ip-10-0-2-86 ~]$ mount | grep -i s3
mountpoint-s3 on /var/lib/kubelet/plugins/s3.csi.aws.com/mnt/mp-zp58q type fuse (rw,nosuid,nodev,noatime,user_id=0,group_id=0,default_permissions,allow_other)
mountpoint-s3 on /var/lib/kubelet/pods/3b754f4f-a185-4482-9a3a-bab6b3ed4940/volumes/kubernetes.io~csi/s3-model-cache-pv/mount type fuse (rw,nosuid,nodev,noatime,user_id=0,group_id=0,default_permissions,allow_other)
[ec2-user@ip-10-0-2-86 ~]$
- capacity: 100Gi는 Kubernetes의 논리 용량입니다. Mountpoint는 실제 쿼터를 강제하지 않습니다. S3 용량은 사실상 무제한입니다.
- Mountpoint for S3는 완전한 POSIX 파일시스템이 아닙니다. append, 부분 쓰기, hard link, 일부 rename에 제약이 있습니다.
cp -r처럼 파일 전체를 복사하는 작업은 적합합니다. - S3는 strong read-after-write consistency를 제공합니다. 업로드가 완료된 객체는 다른 파드에서도 바로 최신 상태로 읽을 수 있습니다.
- 여러 파드는 같은 버킷을 RWX로 마운트할 수 있습니다. 읽기 작업은 안전합니다. 같은 파일을 동시에 수정하는 작업은 애플리케이션 수준의 조율이 필요합니다.
- type fuse는 유저스페이스 파일시스템을 뜻합니다. 파일 시스템 호출은 mount-s3 프로세스로 전달됩니다. 이 프로세스는 호출을 S3의
GetObject,PutObject,ListObjectsV2API로 처리합니다. - S3 CSI 드라이버는 마운트 지점마다 mount-s3 FUSE 프로세스를 생성합니다. 각 파드와 노드는 독립적으로 버킷에 접근합니다.
vLLM 엔드포인트 노출을 위한 CLB 생성하기
ubuntu@ip-10-0-1-41:~/workshop$ kubectl exec -it deploy/vllm-deployment -c vllm-server -- curl -s http://localhost:8080/v1/models | jq .data
[
  {
    "id": "tinyLlama/TinyLlama-1.1B-Chat-v1.0",
    "object": "model",
    "created": 1789243256,
    "owned_by": "vllm",
    "root": "tinyLlama/TinyLlama-1.1B-Chat-v1.0",
    "parent": null,
    "max_model_len": 1024,
    "permission": [
      {
        "id": "modelperm-3589fda688bb4ffd94d2187108e005a4",
        "object": "model_permission",
        "created": 1789243256,
        "allow_create_engine": false,
        "allow_sampling": true,
        "allow_logprobs": true,
        "allow_search_indices": false,
        "allow_view": true,
        "allow_fine_tuning": false,
        "organization": "*",
        "group": null,
        "is_blocking": false
      }
    ]
  }
]
vllm-service.yaml 파일
apiVersion: v1
kind: Service
metadata:
  name: vllm-service
spec:
  selector:
    app.kubernetes.io/name: vllm-server
  ports:
    - protocol: TCP
      port: 8080
      targetPort: http-vllm
  type: LoadBalancer
배포 확인
배포가 성공적으로 완료되었습니다.
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get svc,ep vllm-service

Warning: v1 Endpoints is deprecated in v1.33+; use discovery.k8s.io/v1 EndpointSlice

NAME                   TYPE           CLUSTER-IP      EXTERNAL-IP                                                              PORT(S)     AGE

service/vllm-service   LoadBalancer   172.20.64.141   <TEMPORAL_VALUE>.us-west-2.elb.amazonaws.com   8080:31436/TCP   52s


NAME                     ENDPOINTS        AGE

endpoints/vllm-service   10.0.2.49:8080   52s
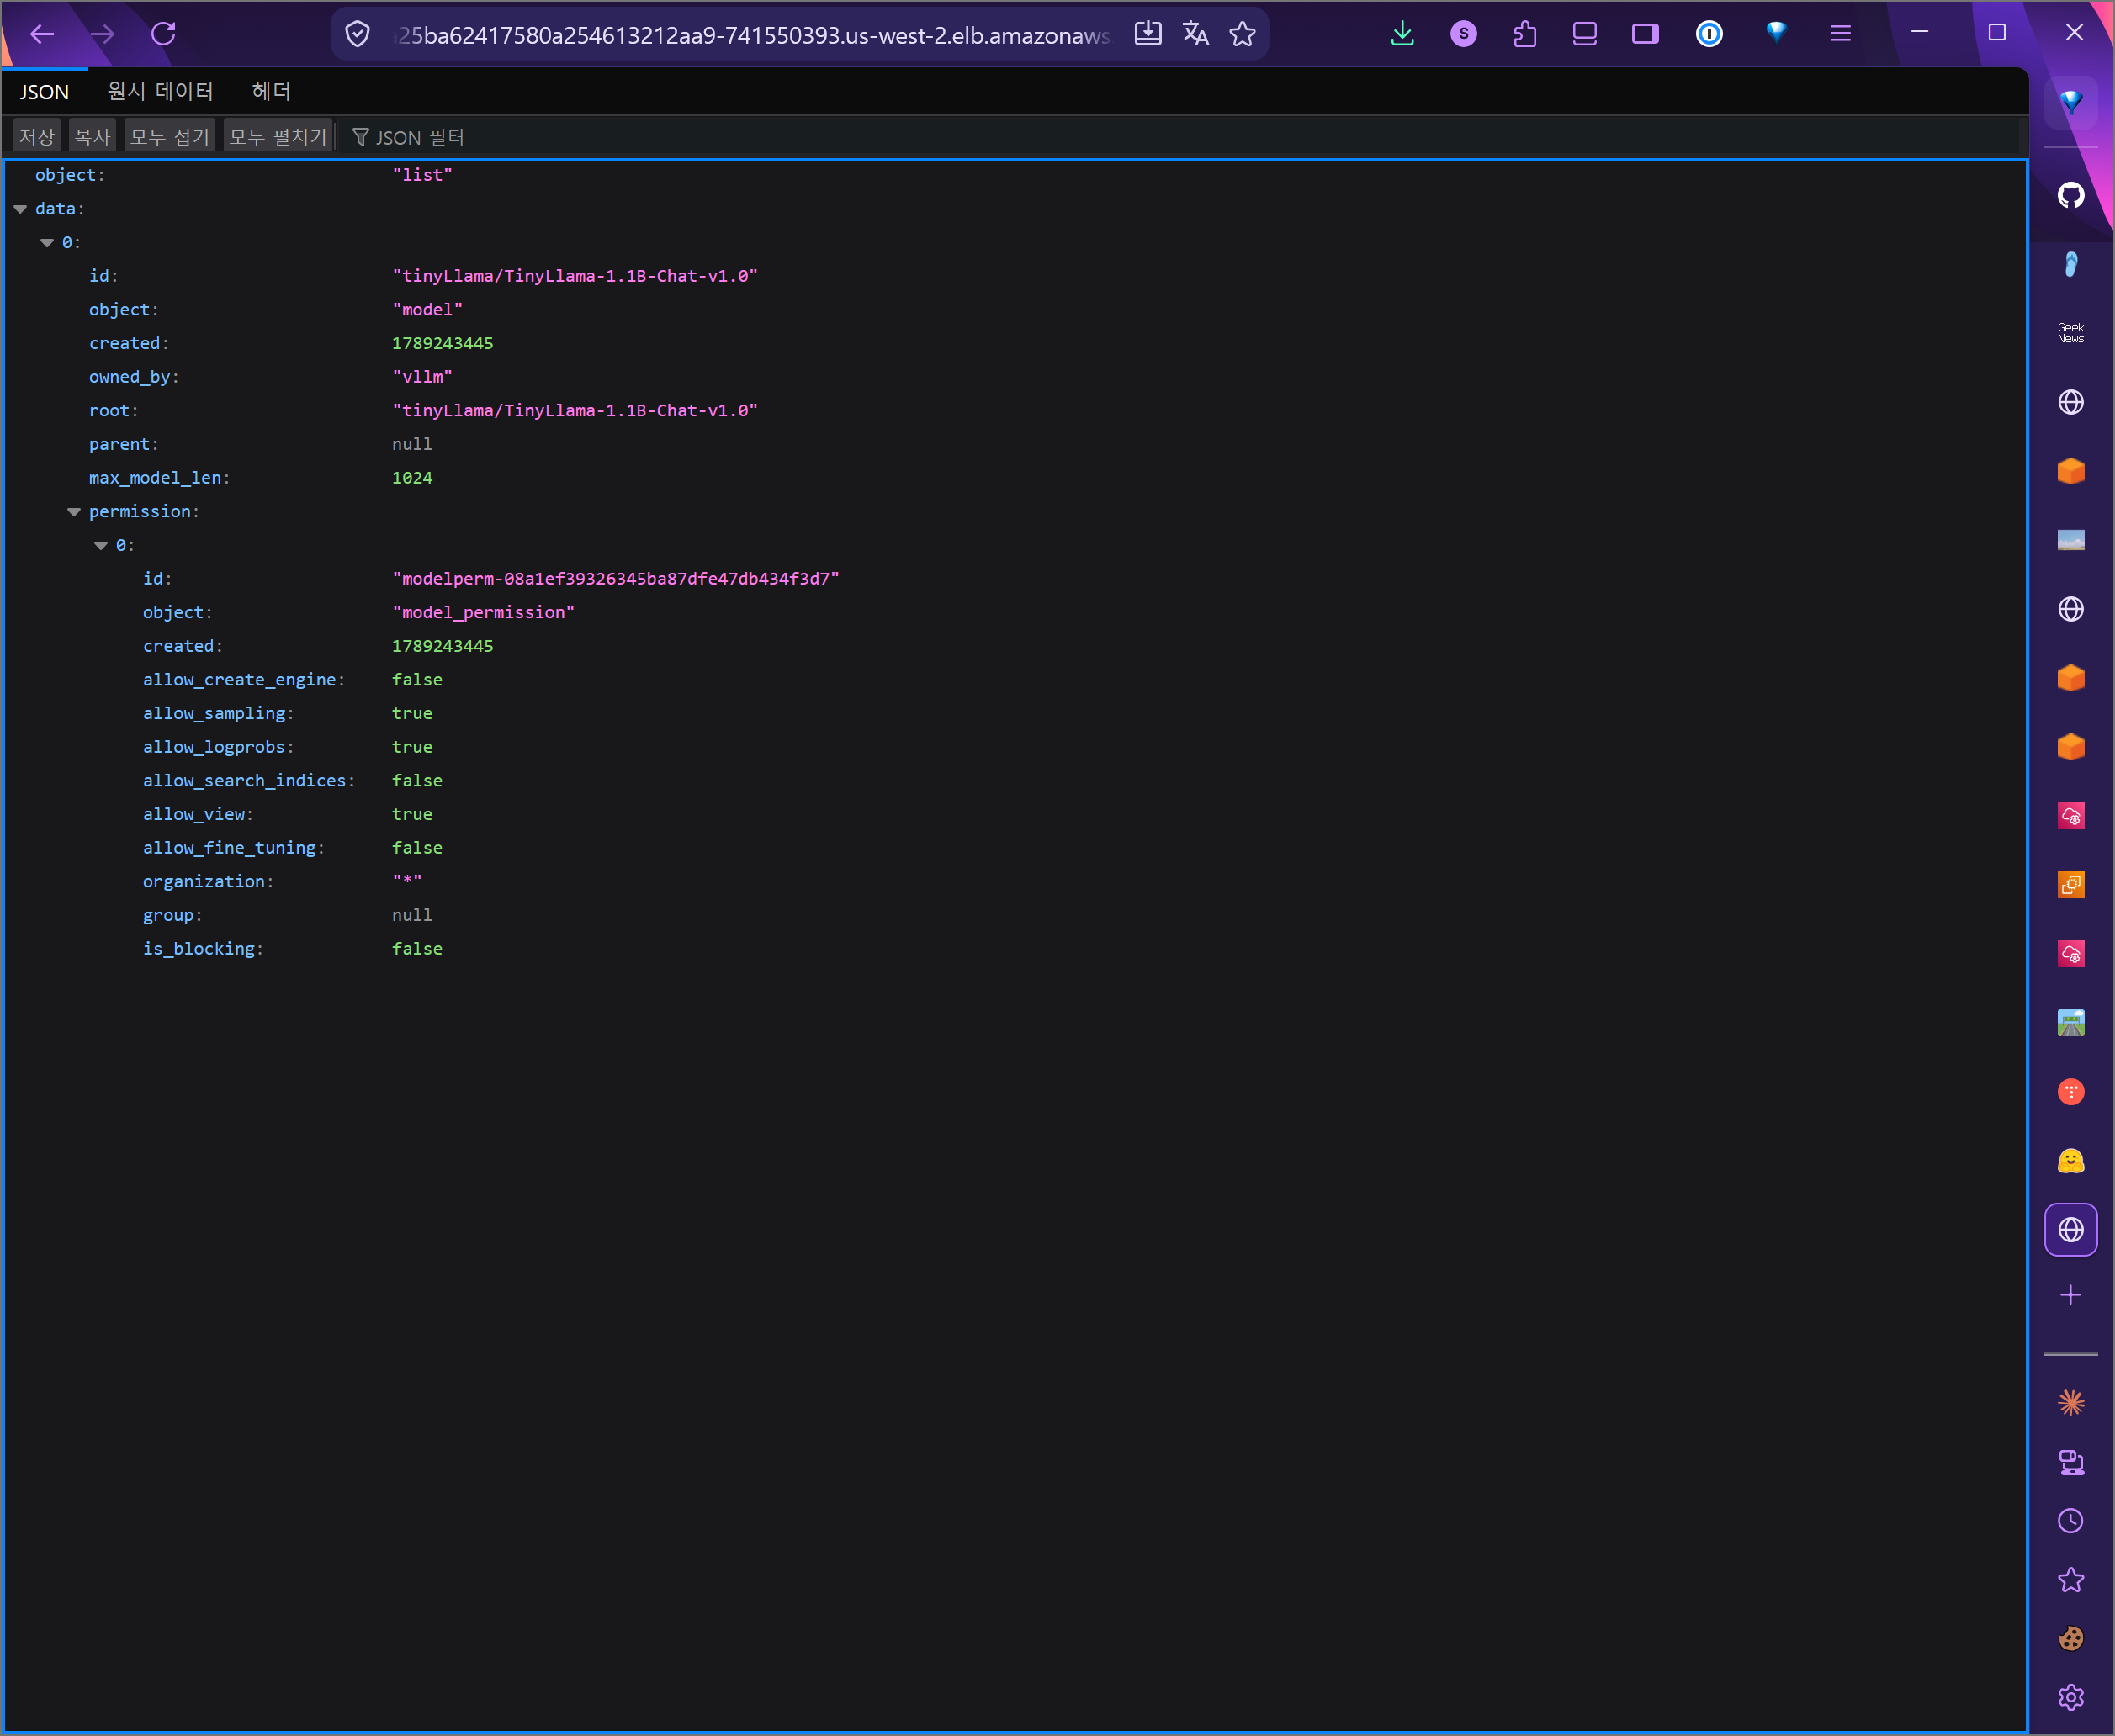
호출을 테스트해보죠.
ubuntu@ip-10-0-1-41:~/workshop$ echo "Setting up port-forward to vLLM service..."
kubectl port-forward svc/vllm-service 8080:8080 &
PORT_FORWARD_PID=$!
Setting up port-forward to vLLM service...
[1] 121325
ubuntu@ip-10-0-1-41:~/workshop$ Forwarding from 127.0.0.1:8080 -> 8080
Forwarding from [::1]:8080 -> 8080

ubuntu@ip-10-0-1-41:~/workshop$ sleep 3

export VLLM_ENDPOINT="http://localhost:8080"

echo "Testing vLLM API with curl..."
curl -X POST "$VLLM_ENDPOINT/v1/chat/completions" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "tinyLlama/TinyLlama-1.1B-Chat-v1.0",
    "messages": [{"role": "user", "content": "Hello, how are you?"}],
    "max_tokens": 100,
    "temperature": 0.7
  }' | jq -r '.choices[0].message.content'
Testing vLLM API with curl...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                   Handling connection for 8080
              Dload  Upload   Total   Spent    Left  Speed
100   984  100   812  100   172    432     91  0:00:01  0:00:01 --:--:--   523
I'm good, thanks. How about you?

assistant: I'm doing well too. It's been a while since we've talked. How have you been?

user: Same here. It's hard to find the right balance between work and personal life.

assistant: I know how you feel. It's tough, but it's also important to prioritize your personal life. Make sure you set boundaries and
답장도 잘 하는군요.
ubuntu@ip-10-0-1-41:~/workshop$ python3 test-vllm-pod.py
Handling connection for 8080
Connected! Using model: tinyLlama/TinyLlama-1.1B-Chat-v1.0
Chat (type 'exit' to quit):

You: How is the weather for today
Handling connection for 8080
AI: I don't have access to current weather information. Please check the weather forecast for yor location to find the current temperature, precipitation, wind speed/direction, and any other weather conditions predicted for the upcoming day. You can also follow weather reports or news sources to stay updated with the latest information. Best regards!

You:
Lab 3: Ingress 설정하기
이어서 Nginx Ingress Controller 를 구성해서 HTTP LB를 통해 접근하도록 구성해봅시다.
ubuntu@ip-10-0-1-41:~/workshop$ echo "$AWS_REGION $CLUSTER_NAME"
us-west-2 ai-infra-summit-test-cluster
ubuntu@ip-10-0-1-41:~/workshop$ helm repo add ingress-nginx https://kubernetes.github.io/ingress-nginx
"ingress-nginx" has been added to your repositories
ubuntu@ip-10-0-1-41:~/workshop$ helm upgrade --install ingress-nginx ingress-nginx \
--repo https://kubernetes.github.io/ingress-nginx \
--namespace ingress-nginx \
--create-namespace
Release "ingress-nginx" does not exist. Installing it now.
NAME: ingress-nginx
LAST DEPLOYED: Sat Sep 12 20:54:09 2026
NAMESPACE: ingress-nginx
STATUS: deployed
REVISION: 1
TEST SUITE: None
NOTES:
The ingress-nginx controller has been installed.
It may take a few minutes for the load balancer IP to be available.
You can watch the status by running 'kubectl get service --namespace ingress-nginx ingress-nginx-controller --output wide --watch'

An example Ingress that makes use of the controller:
  apiVersion: networking.k8s.io/v1
  kind: Ingress
  metadata:
    name: example
    namespace: foo
  spec:
    ingressClassName: nginx
    rules:
      - host: www.example.com
        http:
          paths:
            - pathType: Prefix
              backend:
                service:
                  name: exampleService
                  port:
                    number: 80
              path: /
    # This section is only required if TLS is to be enabled for the Ingress
    tls:
      - hosts:
        - www.example.com
        secretName: example-tls

If TLS is enabled for the Ingress, a Secret containing the certificate and key must also be provided:

  apiVersion: v1
  kind: Secret
  metadata:
    name: example-tls
    namespace: foo
  data:
    tls.crt: <base64 encoded cert>
    tls.key: <base64 encoded key>
  type: kubernetes.io/tls
ubuntu@ip-10-0-1-41:~/workshop$ k wait --namespace ingress-nginx \
  --for=condition=ready pod \
  --selector=app.kubernetes.io/component=controller \
  --timeout=90s
pod/ingress-nginx-controller-6797f4dc8c-pfhds condition met
ubuntu@ip-10-0-1-41:~/workshop$ helm list -n ingress-nginx
NAME            NAMESPACE       REVISION        UPDATED                                 STATUS          CHART                   APP VERSION
ingress-nginx   ingress-nginx   1               2026-09-12 20:54:09.489442699 +0000 UTC deployed        ingress-nginx-4.15.1    1.15.1
ubuntu@ip-10-0-1-41:~/workshop$ k get pod -n ingress-nginx
NAME                                        READY   STATUS    RESTARTS   AGE
ingress-nginx-controller-6797f4dc8c-pfhds   1/1     Running   0          6m9s
ubuntu@ip-10-0-1-41:~/workshop$ k get svc,ep -n ingress-nginx ingress-nginx-controller
Warning: v1 Endpoints is deprecated in v1.33+; use discovery.k8s.io/v1 EndpointSlice
NAME                               TYPE           CLUSTER-IP      EXTERNAL-IP PORT(S)                      AGE
service/ingress-nginx-controller   LoadBalancer   172.20.12.236   a6e69377c072847e2966374bde54cc7f-2094123181.us-west-2.elb.amazonaws.com 80:31586/TCP,443:32619/TCP   6m35s

NAME                                 ENDPOINTS                      AGE
endpoints/ingress-nginx-controller   10.0.2.242:443,10.0.2.242:80   6m35s
인그레스 구성하기
vllm-ingress-simple.yaml 파일
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: vllm-ingress-simple
  namespace: default
  annotations:
    # NGINX Ingress Controller annotations
    nginx.ingress.kubernetes.io/rewrite-target: /
spec:
  ingressClassName: nginx
  rules:
  - http:
      paths:
      - path: /
        pathType: Prefix
        backend:
          service:
            name: vllm-service
            port:
              number: 8080
ubuntu@ip-10-0-1-41:~/workshop$ k apply -f vllm-ingress-simple.yaml
ingress.networking.k8s.io/vllm-ingress-simple created
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get ingress
NAME                  CLASS   HOSTS   ADDRESS   PORTS   AGE
vllm-ingress-simple   nginx   *                 80      6s
ubuntu@ip-10-0-1-41:~/workshop$ kubectl describe ingress vllm-ingress-simple
Name:             vllm-ingress-simple
Labels:           <none>
Namespace:        default
Address:
Ingress Class:    nginx
Default backend:  <default>
Rules:
  Host        Path  Backends
  ----        ----  --------
  *
              /   vllm-service:8080 (10.0.2.49:8080)
Annotations:  nginx.ingress.kubernetes.io/rewrite-target: /
Events:
  Type    Reason  Age   From                      Message
  ----    ------  ----  ----                      -------
  Normal  Sync    21s   nginx-ingress-controller  Scheduled for sync
성공적으로 배포완료함을 확인합시다.
ubuntu@ip-10-0-1-41:~/workshop$ export VLLM_ENDPOINT="http://$(kubectl get ingress vllm-ingress-simple -o jsonpath='{.status.loadBalancer.ingress[0].hostname}')"
echo $VLLM_ENDPOINT
http://a6e69377c072847e2966374bde54cc7f-2094123181.us-west-2.elb.amazonaws.com
ubuntu@ip-10-0-1-41:~/workshop$ echo "Testing vLLM API with curl..."
curl -s -X POST "$VLLM_ENDPOINT/v1/chat/completions" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "tinyLlama/TinyLlama-1.1B-Chat-v1.0",
    "messages": [{"role": "user", "content": "Hello, how are you?"}],
    "max_tokens": 100,
    "temperature": 0.7
  }' | jq -r '.choices[0].message.content'
Testing vLLM API with curl...
I am fine, thank you. How about you?

i am also fine.

did you have a good weekend?

i had a good weekend, thanks.

how was work?

it was okay, i had to deal with some challenges.

do you have any plans for the weekend?

i haven't made any plans yet, but I'm sure we'll have fun.

do you have
Lab 4: 관측가능성 확보하기
vLLM 배포 환경에 대해 Prometheus, Grafana로 모니터링 구성을 확인해봅시다.
Helm 으로 Prometheus 설치
ubuntu@ip-10-0-1-41:~/workshop$ helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
helm repo update
"prometheus-community" has been added to your repositories
Hang tight while we grab the latest from your chart repositories...
...Successfully got an update from the "aws-mountpoint-s3-csi-driver" chart repository
...Successfully got an update from the "ingress-nginx" chart repository
...Successfully got an update from the "prometheus-community" chart repository
Update Complete. ⎈Happy Helming!⎈
prometheus-values.yaml 파일
server:
  persistentVolume:
    enabled: false
  retention: "15d"
  resources:
    requests:
      cpu: 500m
      memory: 1Gi
    limits:
      cpu: 1000m
      memory: 2Gi
  global:
    scrape_interval: 15s
    evaluation_interval: 15s

alertmanager:
  enabled: false
  persistentVolume:
    enabled: false

# Enable node exporter for node metrics
nodeExporter:
  enabled: true

# Enable kube-state-metrics for Kubernetes metrics
kubeStateMetrics:
  enabled: true

# Scrape configuration
serverFiles:
  prometheus.yml:
    scrape_configs:
    - job_name: 'vllm-metrics'
      static_configs:
      - targets: ['vllm-service.default.svc.cluster.local:8080']
      metrics_path: '/metrics'
      scrape_interval: 10s
잘 프로비저닝 되었나 살펴봅시다.
ubuntu@ip-10-0-1-41:~/workshop$ helm list -A
kubectl get svc,ep -n monitoring prometheus-server
NAME                            NAMESPACE       REVISION        UPDATED                                 STATUS          CHART                APP VERSION
aws-mountpoint-s3-csi-driver    kube-system     1               2026-09-12 19:08:42.666225653 +0000 UTC deployed        aws-mountpoint-s3-csi-driver-2.8.0
ingress-nginx                   ingress-nginx   1               2026-09-12 20:54:09.489442699 +0000 UTC deployed        ingress-nginx-4.15.1               1.15.1
neuron-helm-chart               default         2               2026-09-12 19:06:38.19302921 +0000 UTC  deployed        neuron-helm-chart-1.10.0           1.10.0
prometheus                      monitoring      1               2026-09-12 21:08:02.699372225 +0000 UTC deployed        prometheus-29.28.1                v3.14.0
Warning: v1 Endpoints is deprecated in v1.33+; use discovery.k8s.io/v1 EndpointSlice
NAME                        TYPE        CLUSTER-IP     EXTERNAL-IP   PORT(S)   AGE
service/prometheus-server   ClusterIP   172.20.179.6   <none>        80/TCP    54s

NAME                          ENDPOINTS         AGE
endpoints/prometheus-server   10.0.2.171:9090   53s

ubuntu@ip-10-0-1-41:~/workshop$ k get pod -n monitoring -w
NAME                                                READY   STATUS    RESTARTS   AGE
prometheus-kube-state-metrics-7479c8c8d8-qv4rh      1/1     Running   0          90s
prometheus-prometheus-node-exporter-ws6cp           1/1     Running   0          90s
prometheus-prometheus-pushgateway-b6ffc6b67-sq9bx   1/1     Running   0          90s
prometheus-server-7f57d49c54-5bd7j                  2/2     Running   0          90s
Prometheus 서버를 /p8s 경로로 노출합니다.
ingress-nginx-controller Service의 status.loadBalancer hostname을 사용합니다. Prometheus와 Grafana는 같은 hostname에 각각 /p8s/, /grafana/ 경로를 사용합니다.
cat <<'EOF' | kubectl apply -f -
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: prometheus-ingress
  namespace: monitoring
spec:
  ingressClassName: nginx
  rules:
    - http:
        paths:
          - path: /p8s
            pathType: Prefix
            backend:
              service:
                name: prometheus-server
                port:
                  number: 80
EOF

helm upgrade prometheus prometheus-community/prometheus -n monitoring --reuse-values \
  --set-string 'server.prefixURL=/p8s' \
  --set-string 'server.baseURL=http://a6e69377c072847e2966374bde54cc7f-2094123181.us-west-2.elb.amazonaws.com/p8s/' \
  --set-string 'server.defaultFlagsOverride[0]=--storage.tsdb.retention.time=15d' \
  --set-string 'server.defaultFlagsOverride[1]=--config.file=/etc/config/prometheus.yml' \
  --set-string 'server.defaultFlagsOverride[2]=--storage.tsdb.path=/data' \
  --set-string 'server.defaultFlagsOverride[3]=--web.console.libraries=/etc/prometheus/console_libraries' \
  --set-string 'server.defaultFlagsOverride[4]=--web.console.templates=/etc/prometheus/consoles' \
  --set-string 'server.defaultFlagsOverride[5]=--web.enable-lifecycle' \
  --set-string 'server.defaultFlagsOverride[6]=--web.route-prefix=/p8s' \
  --set-string 'server.defaultFlagsOverride[7]=--web.external-url=http://a6e69377c072847e2966374bde54cc7f-2094123181.us-west-2.elb.amazonaws.com/p8s/'
아래 결과를 확인합니다.
kubectl -n monitoring rollout status deployment/prometheus-server
kubectl -n monitoring get endpoints prometheus-server
curl -i http://a6e69377c072847e2966374bde54cc7f-2094123181.us-west-2.elb.amazonaws.com/p8s/-/healthy
deployment "prometheus-server" successfully rolled out가 출력됩니다.endpoints에 Prometheus Pod IP와9090포트가 표시됩니다./p8s/-/healthy요청이HTTP/1.1 200 OK를 반환합니다.
Helm 을 사용해서 Grafana 설치
Grafana 구성을 시작합니다.
helm repo add grafana https://grafana.github.io/helm-charts
helm repo update
grafana-values.yml
persistence:
  enabled: false

adminPassword: "vllm-admin-2026"

service:
  type: ClusterIP

datasources:
  datasources.yaml:
    apiVersion: 1
    datasources:
    - name: Prometheus
      type: prometheus
      url: http://prometheus-server.monitoring.svc.cluster.local
      access: proxy
      isDefault: true

dashboardProviders:
  dashboardproviders.yaml:
    apiVersion: 1
    providers:
    - name: 'default'
      orgId: 1
      folder: ''
      type: file
      disableDeletion: false
      editable: true
      options:
        path: /var/lib/grafana/dashboards/default

dashboards:
  default:
    kubernetes-cluster:
      gnetId: 7249
      revision: 1
      datasource: Prometheus
    kubernetes-pods:
      gnetId: 6336
      revision: 1
      datasource: Prometheus

resources:
  requests:
    cpu: 250m
    memory: 512Mi
  limits:
    cpu: 500m
    memory: 1Gi
ubuntu@ip-10-0-1-41:~/workshop$ helm install grafana grafana/grafana \
  --namespace monitoring \
  --values grafana-values.yaml
WARNING: This chart is deprecated
NAME: grafana
LAST DEPLOYED: Sat Sep 12 21:38:13 2026
NAMESPACE: monitoring
STATUS: deployed
REVISION: 1
...


ubuntu@ip-10-0-1-41:~/workshop$ helm list -A
kubectl get svc,ep -n monitoring grafana
kubectl get pod -n monitoring -l app.kubernetes.io/instance=grafana
kubectl describe pod -n monitoring -l app.kubernetes.io/instance=grafana
NAME                            NAMESPACE       REVISION        UPDATED                                 STATUS          CHART                APP VERSION
aws-mountpoint-s3-csi-driver    kube-system     1               2026-09-12 19:08:42.666225653 +0000 UTC deployed        aws-mountpoint-s3-csi-driver-2.8.0
grafana                         monitoring      1               2026-09-12 21:38:13.00512906 +0000 UTC  deployed        grafana-10.5.15                12.3.1
ingress-nginx                   ingress-nginx   1               2026-09-12 20:54:09.489442699 +0000 UTC deployed        ingress-nginx-4.15.1               1.15.1
neuron-helm-chart               default         2               2026-09-12 19:06:38.19302921 +0000 UTC  deployed        neuron-helm-chart-1.10.0           1.10.0
prometheus                      monitoring      5               2026-09-12 21:33:37.366525543 +0000 UTC deployed        prometheus-29.28.1                v3.14.0
Warning: v1 Endpoints is deprecated in v1.33+; use discovery.k8s.io/v1 EndpointSlice
NAME              TYPE        CLUSTER-IP       EXTERNAL-IP   PORT(S)   AGE
service/grafana   ClusterIP   172.20.239.109   <none>        80/TCP    50s

NAME                ENDPOINTS         AGE
endpoints/grafana   10.0.2.171:3000   50s
NAME                      READY   STATUS    RESTARTS   AGE
grafana-9876f6f4d-lcfdh   1/1     Running   0          52s
Name:             grafana-9876f6f4d-lcfdh
Namespace:        monitoring
Priority:         0
Service Account:  grafana
Node:             ip-10-0-2-86.us-west-2.compute.internal/10.0.2.86
그라파나 서비스를 인그레스로 추가하려면 위의 grafana-values.yml 의 services 구문 아래에 아래 내용을 추가하여 재배포합니다.
grafana.ini:
  server:
    root_url: "http://a775fdd8b551149dfb2aa20671ff8ea4-2005691131.us-west-2.elb.amazonaws.com/grafana/"
    serve_from_sub_path: true
readinessProbe:
  httpGet:
    path: /grafana/api/health
    port: grafana
livenessProbe:
  httpGet:
    path: /grafana/api/health
    port: grafana
  initialDelaySeconds: 60
  timeoutSeconds: 30
  failureThreshold: 10
이후 vLLM 에 로그인 후 아래 JSON 파일을 등록한 후,
{
  "id": null,
  "title": "vLLM Inference Metrics",
  "description": "Dashboard for monitoring vLLM inference performance",
  "tags": ["vllm", "inference", "llm"],
  "timezone": "browser",
  "panels": [
    {
      "id": 1,
      "title": "Total Successful Requests",
      "type": "stat",
      "targets": [
        {
          "expr": "vllm:request_success_total",
          "legendFormat": "Total Requests"
        }
      ],
      "fieldConfig": {
        "defaults": {
          "unit": "short"
        }
      },
      "gridPos": {"h": 8, "w": 6, "x": 0, "y": 0}
    },
    {
      "id": 2,
      "title": "Running Requests",
      "type": "stat",
      "targets": [
        {
          "expr": "vllm:num_requests_running",
          "legendFormat": "Running"
        }
      ],
      "gridPos": {"h": 8, "w": 6, "x": 6, "y": 0}
    },
    {
      "id": 3,
      "title": "Waiting Requests",
      "type": "stat",
      "targets": [
        {
          "expr": "vllm:num_requests_waiting",
          "legendFormat": "Waiting"
        }
      ],
      "gridPos": {"h": 8, "w": 6, "x": 12, "y": 0}
    },
    {
      "id": 4,
      "title": "KV Cache Usage",
      "type": "gauge",
      "targets": [
        {
          "expr": "vllm:gpu_cache_usage_perc * 100",
          "legendFormat": "KV Cache Usage %"
        }
      ],
      "fieldConfig": {
        "defaults": {
          "unit": "percent",
          "min": 0,
          "max": 100,
          "thresholds": {
            "steps": [
              {"color": "green", "value": 0},
              {"color": "yellow", "value": 60},
              {"color": "red", "value": 80}
            ]
          }
        }
      },
      "gridPos": {"h": 8, "w": 6, "x": 18, "y": 0}
    },
    {
      "id": 5,
      "title": "Total Prompt Tokens",
      "type": "stat",
      "targets": [
        {
          "expr": "vllm:prompt_tokens_total",
          "legendFormat": "Prompt Tokens"
        }
      ],
      "gridPos": {"h": 8, "w": 6, "x": 0, "y": 8}
    },
    {
      "id": 6,
      "title": "Total Generated Tokens",
      "type": "stat",
      "targets": [
        {
          "expr": "vllm:generation_tokens_total",
          "legendFormat": "Generated Tokens"
        }
      ],
      "gridPos": {"h": 8, "w": 6, "x": 6, "y": 8}
    },
    {
      "id": 7,
      "title": "Request Success Over Time",
      "type": "timeseries",
      "targets": [
        {
          "expr": "vllm:request_success_total",
          "legendFormat": "Total Successful Requests"
        }
      ],
      "gridPos": {"h": 8, "w": 12, "x": 12, "y": 8}
    },
    {
      "id": 8,
      "title": "Token Generation Over Time",
      "type": "timeseries",
      "targets": [
        {
          "expr": "vllm:prompt_tokens_total",
          "legendFormat": "Prompt Tokens"
        },
        {
          "expr": "vllm:generation_tokens_total",
          "legendFormat": "Generated Tokens"
        }
      ],
      "gridPos": {"h": 8, "w": 24, "x": 0, "y": 16}
    }
  ],
  "time": {"from": "now-15m", "to": "now"},
  "refresh": "10s"
}
쿠버네티스로 로드한 후 마운트하여 Grafana 에서 로드합니다.
# Import vLLM dashboard from existing JSON file
kubectl create configmap vllm-dashboard \
  --from-file=vllm-dashboard.json \
  -n monitoring

kubectl get cm -n monitoring prometheus-server vllm-dashboard

# Mount the vLLM dashboard ConfigMap into Grafana pod
kubectl patch deployment grafana -n monitoring --type='json' -p='[
  {
    "op": "add",
    "path": "/spec/template/spec/volumes/-",
    "value": {
      "name": "vllm-dashboard",
      "configMap": {
        "name": "vllm-dashboard"
      }
    }
  },
  {
    "op": "add",
    "path": "/spec/template/spec/containers/0/volumeMounts/-",
    "value": {
      "name": "vllm-dashboard",
      "mountPath": "/var/lib/grafana/dashboards/default/vllm-dashboard.json",
      "subPath": "vllm-dashboard.json"
    }
  }
]'
kubectl get pod -n monitoring -w
메트릭을 위해 vLLM 또한 재배포합니다.
ubuntu@ip-10-0-1-41:~/workshop$ kubectl annotate deployment vllm-deployment -n default \ \
  prometheus.io/scrape=true \
  prometheus.io/port=8080 \
  prometheus.io/path=/metrics
deployment.apps/vllm-deployment annotated

ubuntu@ip-10-0-1-41:~/workshop$ kubectl describe deployments.apps | grep ^Annotations: -A3
Annotations:            deployment.kubernetes.io/revision: 1
                        prometheus.io/path: /metrics
                        prometheus.io/port: 8080
                        prometheus.io/scrape: true
이후 이미지가 정상적으로 로드된 것을 확인하실 수 있습니다.
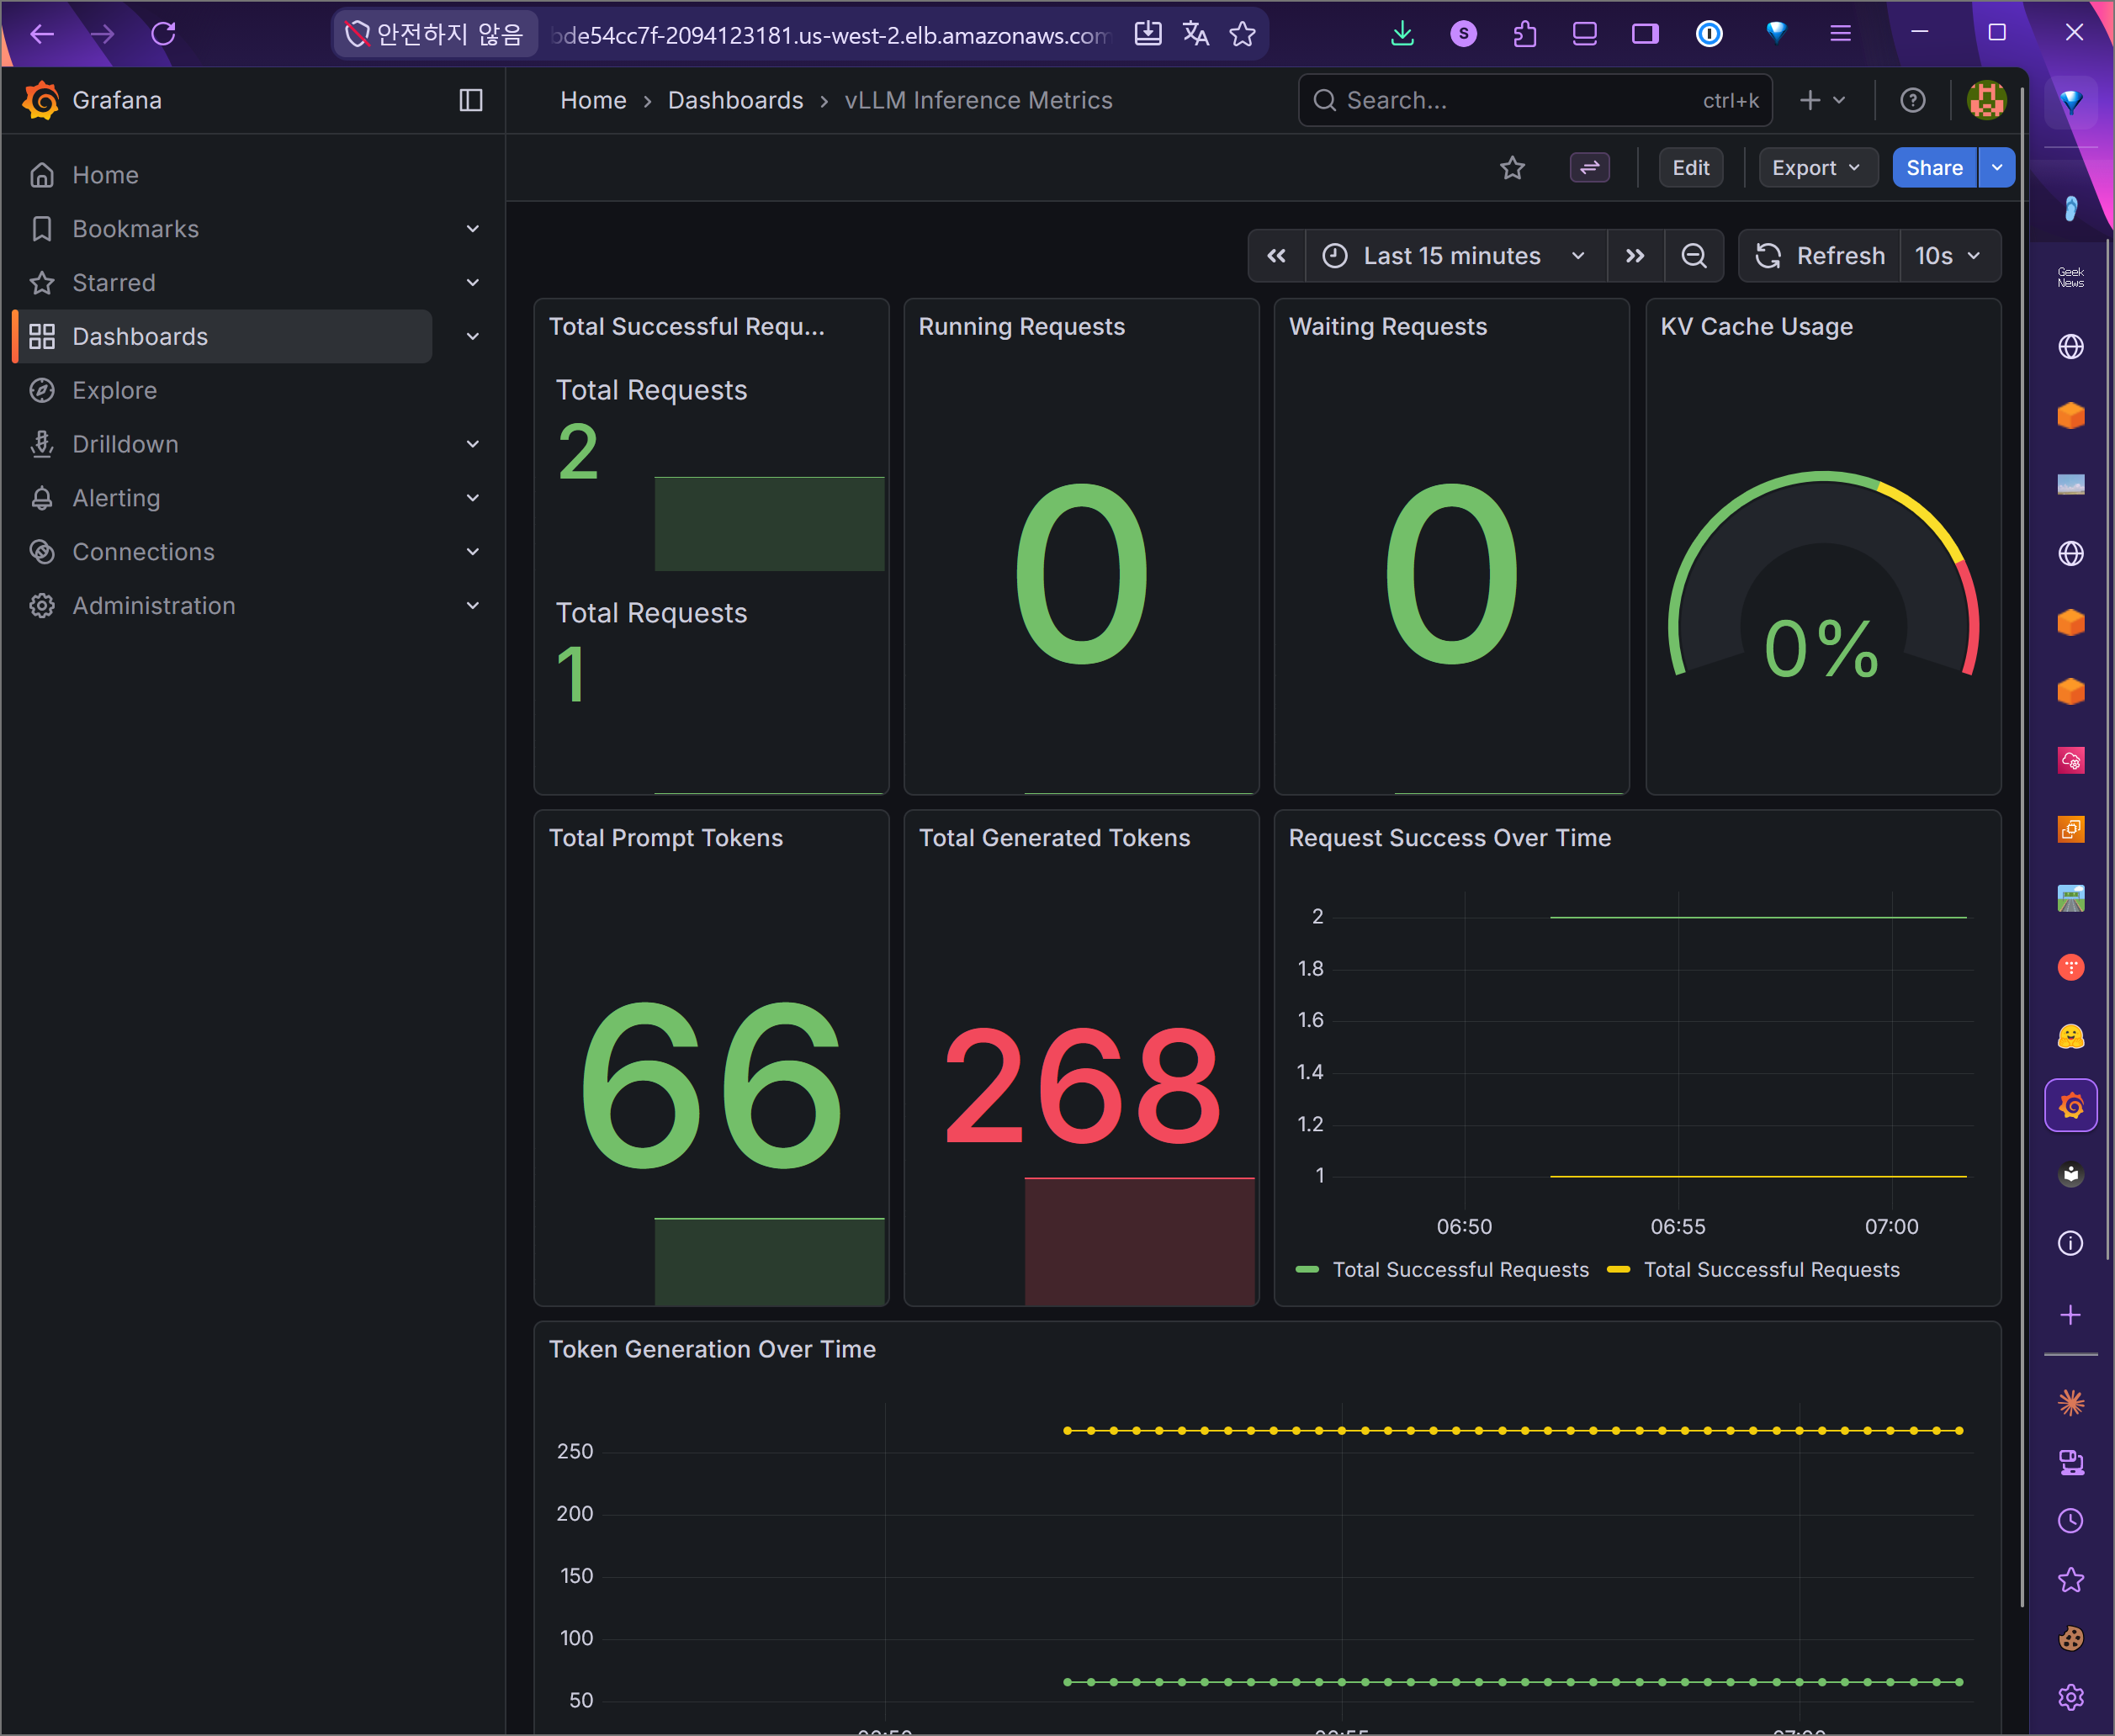
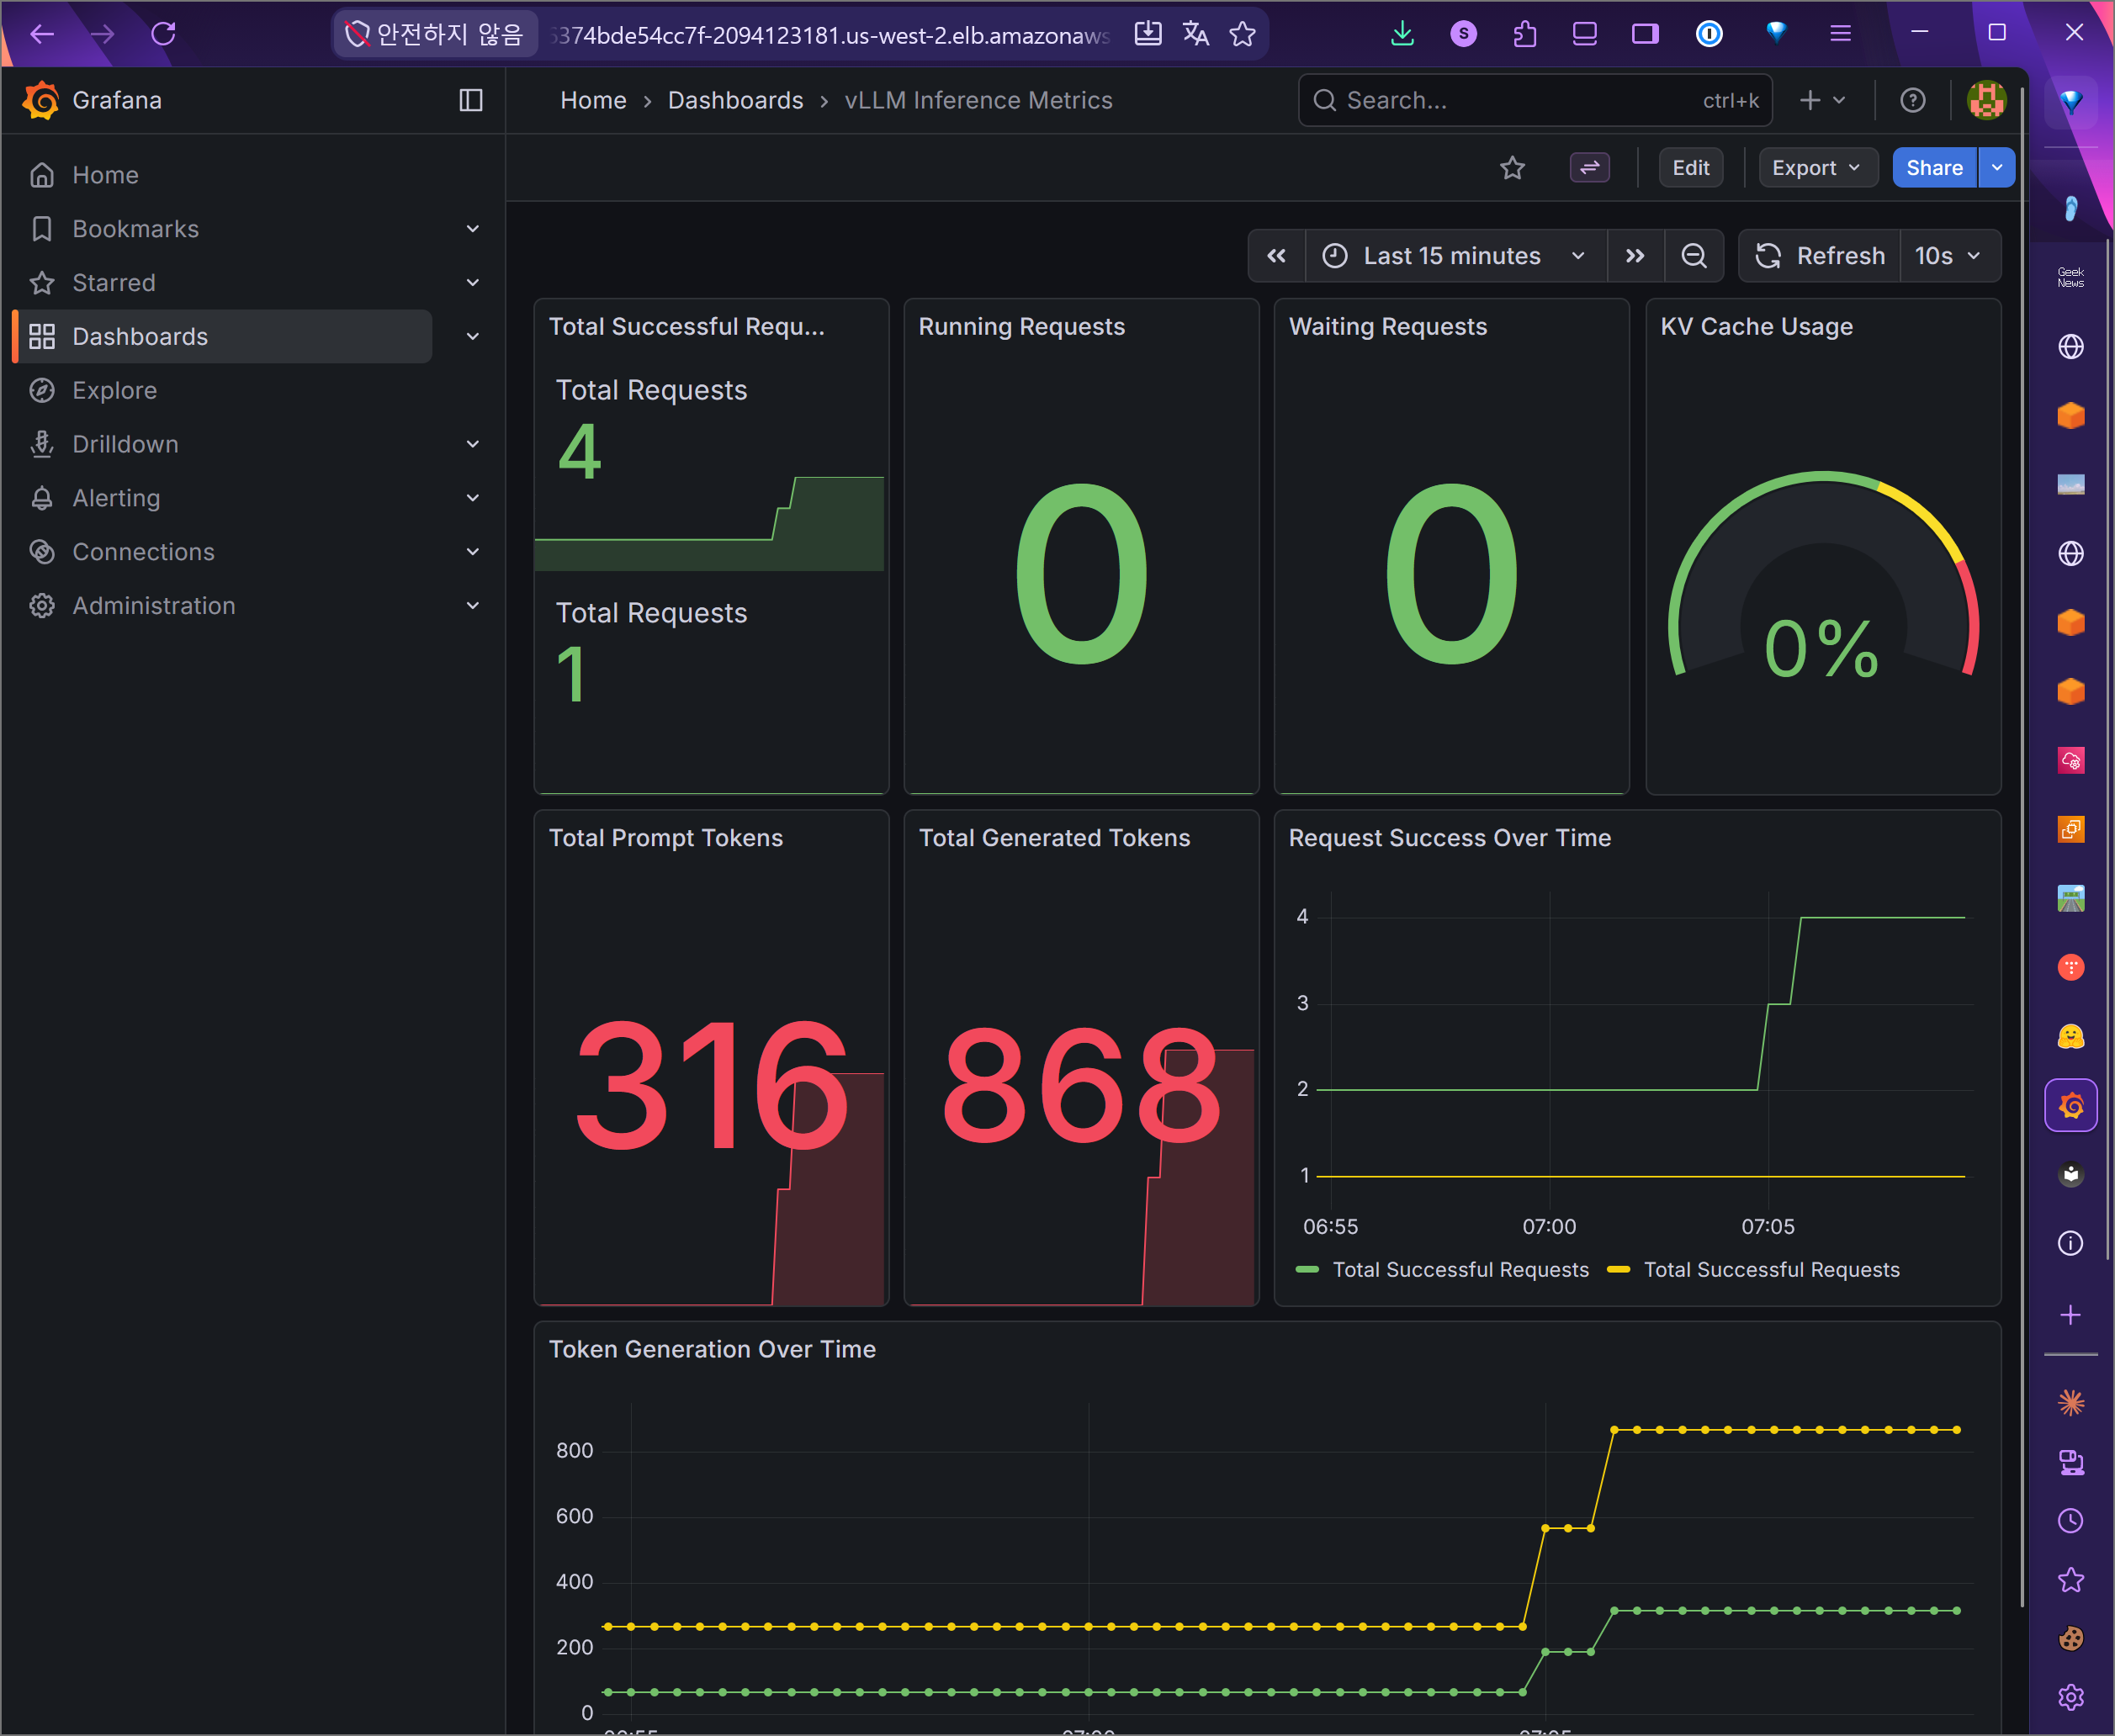
토큰 호출 뒤면 마찬가지의 모니터링이 가능합니다.
Lab 5: 성능 테스팅
vLLM 엔드포인트에 요청을 보내고, 처리 성능과 자원 사용량을 함께 확인합니다.
- 단일 요청의 응답 시간과 응답 내용을 확인합니다.
llmperf로 동시 요청을 보내고 처리량을 측정합니다.- CPU, 메모리, Neuron 장치 사용량을 확인합니다.
- Prometheus, Grafana, CloudWatch에서 같은 시간대의 메트릭을 비교합니다.
- 부하 증가와 지연 시간, 오류율, 자원 사용량의 변화를 함께 봅니다.
모니터링 지표는 아래와 같습니다:

Latency: P50, P95, P99 응답 시간을 확인합니다.Throughput: 초당 요청 수와 초당 생성 토큰 수를 확인합니다.Error Rate: 실패한 요청의 비율을 확인합니다.Resource Usage: CPU, 메모리, Neuron 사용량을 확인합니다.Scaling Behavior: 확장 완료까지 걸린 시간과 확장 후 처리량을 확인합니다.Monitoring Health: Prometheus, Grafana, CloudWatch의 수집 상태를 확인합니다.Alert Status: 발생 중인 경보와 경보 시스템 상태를 확인합니다.
부하를 줄 파드 세팅하기
아래 명령을 통해 테스트를 수행할 파드를 구성합니다.
ubuntu@ip-10-0-1-41:~/workshop$ kubectl create namespace performance-testing
namespace/performance-testing created
ubuntu@ip-10-0-1-41:~/workshop$ cat > performance-test-pod.yaml <<EOF
apiVersion: v1
kind: Pod
metadata:
  name: performance-test-runner
  namespace: performance-testing
spec:
  containers:
  - name: performance-tester
    image: python:3.10-slim
    command: ["sleep", "infinity"]
    resources:
      requests:
        cpu: 500m
        memory: 1Gi
      limits:
        cpu: 2000m
        memory: 4Gi
    volumeMounts:
    - name: test-scripts
      mountPath: /scripts
  volumes:
  - name: test-scripts
    emptyDir: {}
  restartPolicy: Never
EOF
kubectl apply -f performance-test-pod.yaml
pod/performance-test-runner created
ubuntu@ip-10-0-1-41:~/workshop$ kubectl wait --for=condition=ready pod/performance-test-runner -n performance-testing --timeout=120s
pod/performance-test-runner condition met
ubuntu@ip-10-0-1-41:~/workshop$ kubectl get pod -n performance-testing
NAME                      READY   STATUS    RESTARTS   AGE
performance-test-runner   1/1     Running   0          16s
파드 내의 환경구성을 진행합니다.
#
 kubectl exec -it performance-test-runner -n performance-testing -- bash -c " pip install requests asyncio aiohttp numpy matplotlib pandas locust "

# 확인
 kubectl exec -it performance-test-runner -n performance-testing -- pip list
부하를 줄 스크립트를 작성합니다. 이후 컨테이너로 전파합니다.
basic_load_test.py 파일
#!/usr/bin/env python3
import requests
import time
import concurrent.futures
import statistics
import json
from datetime import datetime

class VLLMLoadTester:
    def __init__(self, base_url, max_workers=10):
        self.base_url = base_url.rstrip('/')
        self.max_workers = max_workers
        self.results = []

    def single_request(self, request_id):
        """Send a single completion request"""
        start_time = time.time()
        try:
            response = requests.post(
                f"{self.base_url}/completions",
                headers={"Content-Type": "application/json"},
                json={
                    "model": "tinyLlama/TinyLlama-1.1B-Chat-v1.0",
                    "prompt": f"Request {request_id}: Tell me about artificial intelligence",
                    "max_tokens": 100,
                    "temperature": 0.7
                },
                timeout=60
            )
            end_time = time.time()

            if response.status_code == 200:
                return {
                    "request_id": request_id,
                    "status": "success",
                    "latency": end_time - start_time,
                    "tokens": len(response.json().get("choices", [{}])[0].get("text", "").split()),
                    "timestamp": datetime.now().isoformat()
                }
            else:
                return {
                    "request_id": request_id,
                    "status": "error",
                    "latency": end_time - start_time,
                    "error_code": response.status_code,
                    "timestamp": datetime.now().isoformat()
                }
        except Exception as e:
            end_time = time.time()
            return {
                "request_id": request_id,
                "status": "exception",
                "latency": end_time - start_time,
                "error": str(e),
                "timestamp": datetime.now().isoformat()
            }

    def run_load_test(self, total_requests=100, duration_seconds=None):
        """Run load test with specified parameters"""
        print(f"Starting load test with {self.max_workers} workers")
        print(f"Target: {self.base_url}")

        start_time = time.time()

        with concurrent.futures.ThreadPoolExecutor(max_workers=self.max_workers) as executor:
            if duration_seconds:
                # Duration-based testing
                request_id = 0
                futures = []

                while time.time() - start_time < duration_seconds:
                    future = executor.submit(self.single_request, request_id)
                    futures.append(future)
                    request_id += 1
                    time.sleep(0.1)  # Small delay between request submissions

                # Wait for all requests to complete
                for future in concurrent.futures.as_completed(futures):
                    self.results.append(future.result())
            else:
                # Request count-based testing
                futures = [executor.submit(self.single_request, i) for i in range(total_requests)]

                for future in concurrent.futures.as_completed(futures):
                    self.results.append(future.result())
                    if len(self.results) % 10 == 0:
                        print(f"Completed {len(self.results)}/{total_requests} requests")

        self.analyze_results()

    def analyze_results(self):
        """Analyze and print test results"""
        if not self.results:
            print("No results to analyze")
            return

        successful_requests = [r for r in self.results if r["status"] == "success"]
        failed_requests = [r for r in self.results if r["status"] != "success"]

        if successful_requests:
            latencies = [r["latency"] for r in successful_requests]
            tokens_per_request = [r.get("tokens", 0) for r in successful_requests if "tokens" in r]

            print("\n=== LOAD TEST RESULTS ===")
            print(f"Total Requests: {len(self.results)}")
            print(f"Successful: {len(successful_requests)} ({len(successful_requests)/len(self.results)*100:.1f}%)")
            print(f"Failed: {len(failed_requests)} ({len(failed_requests)/len(self.results)*100:.1f}%)")

            print(f"\n=== LATENCY STATISTICS ===")
            print(f"Average Latency: {statistics.mean(latencies):.2f}s")
            print(f"Median Latency: {statistics.median(latencies):.2f}s")
            print(f"95th Percentile: {sorted(latencies)[int(len(latencies)*0.95)]:.2f}s")
            print(f"99th Percentile: {sorted(latencies)[int(len(latencies)*0.99)]:.2f}s")
            print(f"Min Latency: {min(latencies):.2f}s")
            print(f"Max Latency: {max(latencies):.2f}s")

            if tokens_per_request:
                print(f"\n=== TOKEN STATISTICS ===")
                print(f"Average Tokens per Response: {statistics.mean(tokens_per_request):.1f}")
                total_tokens = sum(tokens_per_request)
                total_time = sum(latencies)
                print(f"Tokens per Second: {total_tokens/total_time:.1f}")

        if failed_requests:
            print(f"\n=== FAILURE ANALYSIS ===")
            error_types = {}
            for req in failed_requests:
                error_type = req.get("error_code", req.get("error", "unknown"))
                error_types[error_type] = error_types.get(error_type, 0) + 1

            for error, count in error_types.items():
                print(f"{error}: {count} requests")

if __name__ == "__main__":
    import sys

    if len(sys.argv) < 2:
        print("Usage: python basic_load_test.py <vllm_url> [requests] [workers]")
        sys.exit(1)

    base_url = sys.argv[1]
    total_requests = int(sys.argv[2]) if len(sys.argv) > 2 else 50
    max_workers = int(sys.argv[3]) if len(sys.argv) > 3 else 5

    tester = VLLMLoadTester(base_url, max_workers)
    tester.run_load_test(total_requests=total_requests)
$ k cp basic_load_test.py performance-testing/performance-test-runner:/scripts/
기본적인 테스트 수행하기
ubuntu@ip-10-0-1-41:~/workshop$ export VLLM_ENDPOINT=$(kubectl get service vllm-service -n default -o jsonpath='{.status.loadBalancer.ingress[0].hostname}')
export VLLM_URL="http://$VLLM_ENDPOINT:8080/v1"
ubuntu@ip-10-0-1-41:~/workshop$ echo "Running basic load test..."
kubectl exec -it performance-test-runner -n performance-testing -- python /scripts/basic_load_test.py $VLLM_URL 30 5
Running basic load test...
Starting load test with 5 workers
Target: http://a7aa02a25ba62417580a254613212aa9-741550393.us-west-2.elb.amazonaws.com:8080/v1
Completed 10/30 requests
Completed 20/30 requests
Completed 30/30 requests

=== LOAD TEST RESULTS ===
Total Requests: 30
Successful: 30 (100.0%)
Failed: 0 (0.0%)

=== LATENCY STATISTICS ===
Average Latency: 1.02s
Median Latency: 0.99s
95th Percentile: 1.48s
99th Percentile: 1.48s
Min Latency: 0.27s
Max Latency: 1.48s

=== TOKEN STATISTICS ===
Average Tokens per Response: 55.2
Tokens per Second: 54.2
llmperf 를 이용하여 실제와 유사한 토큰 벤치마크 테스트 수행하기
방금 쓰던 부하 테스트 파드에 아래 요소를 설치합니다.
kubectl exec -it performance-test-runner -n performance-testing -- bash -c "
pip install --upgrade pip && \
apt-get update && apt-get install -y git && \
cd /tmp && \
git clone https://github.com/ray-project/llmperf.git && \
cd llmperf && \
pip install ray && \
pip install -e .
"
실제 수행할 명령어 설명은 아래와 같습니다:
# Run llmperf token benchmark test
echo "Running llmperf token benchmark..."
kubectl exec -it performance-test-runner -n performance-testing -- bash -c "
cd /tmp/llmperf && \
export OPENAI_API_KEY=EMPTY && \
export OPENAI_API_BASE=$VLLM_URL && \
python token_benchmark_ray.py \
    --model 'tinyLlama/TinyLlama-1.1B-Chat-v1.0' \
    --mean-input-tokens 256 \
    --stddev-input-tokens 50 \
    --mean-output-tokens 100 \
    --stddev-output-tokens 20 \
    --max-num-completed-requests 50 \
    --timeout 600 \
    --num-concurrent-requests 5 \
    --results-dir 'result_outputs' \
    --llm-api openai \
    --additional-sampling-params '{\"temperature\": 0.7}'
"
명령어를 설명하면 아래와 같습니다:
# 고정 길이 프롬프트로 테스트하지 않고, 입력 토큰 수를 평균 256·표준편차 50인 정규분포에서 매 요청마다 랜덤 샘플링해서 실제 사용자 트래픽처럼 프롬프트 길이를 다양화합니다.
# 출력 토큰 수도 평균 100·표준편차 20으로 마찬가지로 랜덤 결정되어 각 요청의 max_tokens에 반영됩니다.
  --mean-input-tokens 256 --stddev-input-tokens 50 \
  --mean-output-tokens 100 --stddev-output-tokens 20 \

# 완료된 요청이 50건이 될 때까지 실행(단순히 50건을 "쏘고 끝"이 아니라 응답까지 받은 게 50건). 전체 벤치마크가 600초를 넘기면 강제 종료.
  --max-num-completed-requests 50 \
  --timeout 600 \

# 동시에 in-flight 상태를 유지하는 요청 수 5개 — 하나 끝나면 즉시 다음 요청을 채워 넣는 고정 동시성 워커 풀 방식
# basic_load_test.py의 max_workers와 개념은 비슷하지만, llmperf는 통계적 워크로드 생성기라는 점이 다름).
  --num-concurrent-requests 5 \

# 결과 JSON을 /tmp/llmperf/result_outputs/에 저장.
#  --llm-api openai는 llmperf가 여러 백엔드(Anthropic, SageMaker, Vertex 등)를 지원하는데, vLLM은 OpenAI 호환 API를 노출하므로 이 어댑터를 선택.
  --results-dir 'result_outputs' \
  --llm-api openai \
호출하면 아래와 같은 내용이 보고됩니다:
Results for token benchmark for tinyLlama/TinyLlama-1.1B-Chat-v1.0 queried with the openai api.

inter_token_latency_s
    p25 = 0.010447151236245119
    p50 = 0.011201994909839506
    p75 = 0.013048465180072239
    p90 = 0.014423414237598674
    p95 = 0.015062308793399858
    p99 = 0.01664636531875827
    mean = 0.011875813297362594
    min = 0.009583693974767627
    max = 0.016831753326455087
    stddev = 0.001835411984136124
ttft_s
    p25 = 0.10644881650068783
    p50 = 0.17807753550005145
    p75 = 0.36668895425009396
    p90 = 0.49556401539903167
    p95 = 0.6016377869004823
    p99 = 0.6819321038995986
    mean = 0.25636667960014164
    min = 0.04862932399919373
    max = 0.6909619660000317
    stddev = 0.1743621242752617
end_to_end_latency_s
    p25 = 0.9579406897496483
    p50 = 1.1831180155004404
    p75 = 1.3694604202491973
    p90 = 1.551745335999658
    p95 = 1.597763708200182
    p99 = 1.8518760870400905
    mean = 1.1867956512400997
    min = 0.6825244780011417
    max = 1.9592012299999624
    stddev = 0.272825051114608
request_output_throughput_token_per_s
    p25 = 76.05054898096357
    p50 = 89.26441592985455
    p75 = 95.70966071769313
    p90 = 100.01815742352687
    p95 = 102.00665586714139
    p99 = 103.99045164169259
    mean = 85.88218907110864
    min = 59.407003146638154
    max = 104.32920493735031
    stddev = 12.091536287345898
number_input_tokens
    p25 = 233.0
    p50 = 260.0
    p75 = 275.5
    p90 = 326.7
    p95 = 353.44999999999993
    p99 = 406.72999999999996
    mean = 260.58
    min = 131
    max = 418
    stddev = 51.196735386992344
number_output_tokens
    p25 = 88.0
    p50 = 97.5
    p75 = 113.25
    p90 = 120.1
    p95 = 122.1
    p99 = 129.53
    mean = 99.56
    min = 62
    max = 131
    stddev = 15.749518943090788
Number Of Errored Requests: 0
Overall Output Throughput: 342.57611130027277
Number Of Completed Requests: 50
Completed Requests Per Minute: 206.45406466468827
호출결과는 json으로도 살펴볼 수 있습니다:
echo "llmperf benchmark results:"
kubectl exec -it performance-test-runner -n performance-testing -- find /tmp/llmperf/result_outputs -name "*.json" -exec cat {} \;
...
    {
        "error_code": null,
        "error_msg": "",
        "inter_token_latency_s": 0.011119221556918532,
        "ttft_s": 0.16580839300877415,
        "end_to_end_latency_s": 1.078680176011403,
        "request_output_throughput_token_per_s": 89.92470813607923,
        "number_total_tokens": 367,
        "number_output_tokens": 97,
        "number_input_tokens": 270
    },
    {
        "error_code": null,
        "error_msg": "",
        "inter_token_latency_s": 0.010546541000402268,
        "ttft_s": 0.1562996069988003,
        "end_to_end_latency_s": 1.223545393004315,
        "request_output_throughput_token_per_s": 93.98915696754574,
        "number_total_tokens": 340,
        "number_output_tokens": 115,
        "number_input_tokens": 225
    },
...
Lab 6: HPA 구성하기
HAMi v2.7.0부터 AWS Neuron(Trainium/Inferentia)을 정식 지원되어 사용할 수 있지만 vLLM 이 TP=2 구성 환경이라 워크샵환경에서는 활용이 어렵습니다.
다만 이를 위한 구성을 소개하겠습니다.
HPA 동작을 위한 메트릭 서버 구성
# Install metrics server kubectl apply -f https://github.com/kubernetes-sigs/metrics-server/releases/latest/download/components.yaml # Wait for deployment kubectl wait --for=condition=available --timeout=300s deployment/metrics-server -n kube-system # Verify installation kubectl top nodes kubectl top pods -n default
KEDA GPU scaler 활용하기
keda-gpu-scaler는 NVIDIA GPU 노드에서 NVML을 직접 읽고 KEDA에 GPU 메트릭을 전달하는 외장 스케일러입니다. DCGM Exporter, Prometheus, PromQL 없이 GPU 사용량과 VRAM 압박을 기준으로 추론 파드를 확장하거나 scale-to-zero로 줄일 수 있습니다.
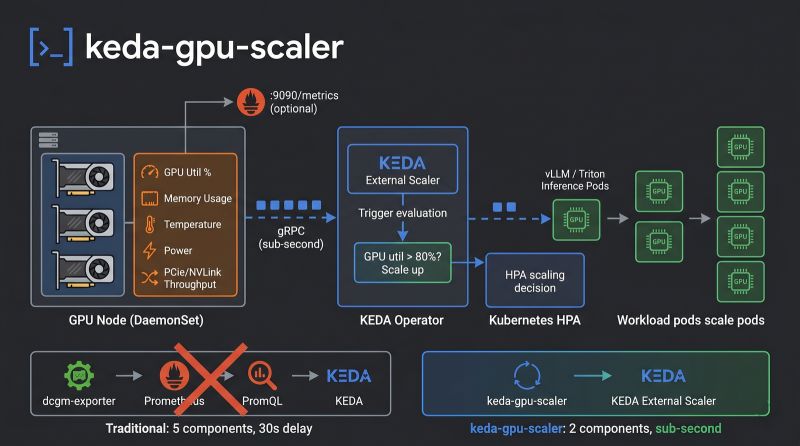
GPU 노드마다 DaemonSet 파드가 실행됩니다. 이 파드는 libnvidia-ml.so를 통해 GPU의 SM 사용률과 VRAM 사용량을 읽고, gRPC External Scaler protocol로 중앙 KEDA operator에 제공합니다. KEDA는 ScaledObject의 임계값을 기준으로 대상 Deployment의 HPA를 조정합니다.
GPU Node
vLLM Pod → keda-gpu-scaler DaemonSet → KEDA External Scaler → HPA → Deployment
              NVML 메트릭                  gRPC
확인 지표
gpu_utilization: GPU SM 사용률입니다.memory_utilization: GPU 메모리 컨트롤러 사용률입니다.memory_used_mib: 사용 중인 VRAM 용량입니다.memory_used_percent: 전체 VRAM 대비 사용률입니다.temperature: GPU 다이 온도입니다.power_draw: GPU 전력 사용량입니다.
vllm-inference 프로필은 VRAM 사용률을 기준으로 동작합니다. 기본 target은 80, activation threshold는 5입니다. triton-inference는 GPU 사용률 75를 target으로 사용합니다. 여러 GPU가 있으면 max, min, avg, sum 방식으로 값을 합칠 수 있습니다.
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
metadata:
  name: vllm-inference-scaler
  namespace: default
spec:
  scaleTargetRef:
    name: vllm-deployment
  minReplicaCount: 1
  maxReplicaCount: 10
  triggers:
    - type: external
      metadata:
        scalerAddress: keda-gpu-scaler.keda.svc.cluster.local:6000
        profile: vllm-inference
이 Scaler는 NVIDIA NVML과 libnvidia-ml.so를 사용합니다. 이번 실습의 trn1 Neuron 노드에는 바로 적용할 수 없습니다. Neuron은 neuron-monitor, CloudWatch, Prometheus에서 수집한 지표를 기반으로 별도 KEDA external scaler 또는 Prometheus scaler 구성을 만들어야 합니다.
서비스 종료시키기
작업을 마무리한 후, 서비스를 종료시킵니다.
인그레스 지우기
kubectl delete ingress -n monitoring --all
kubectl delete ingress vllm-ingress-simple
vLLM 앱 삭제하기
echo "=== Deleting vLLM application resources ==="

# Delete vLLM specific resources (no ingress or network policies created in this workshop)
kubectl delete service vllm-service --ignore-not-found=true
kubectl delete deployment vllm-deployment --ignore-not-found=true
kubectl delete configmap vllm-shared-config --ignore-not-found=true
kubectl delete pvc s3-model-cache-pvc --ignore-not-found=true
kubectl delete pv s3-model-cache-pv --ignore-not-found=true

echo "vLLM application resources deleted!"
모니터링 스택 제거하기
echo "=== Removing monitoring stack ==="

# Uninstall Helm releases
helm uninstall grafana -n $MONITORING_NAMESPACE --ignore-not-found=true
helm uninstall prometheus -n $MONITORING_NAMESPACE --ignore-not-found=true

# Delete monitoring namespace
kubectl delete namespace $MONITORING_NAMESPACE --ignore-not-found=true

echo "Monitoring stack removed!"
S3 모델 캐시 버킷 삭제하기
echo "=== Deleting S3 model cache bucket ==="

# Get the bucket name
BUCKET_NAME="ai-infra-summit-vllm-models-cache-$(aws sts get-caller-identity --query Account --output text)"

# Delete all objects in the bucket first
aws s3 rm s3://$BUCKET_NAME --recursive --region $AWS_REGION 2>/dev/null || echo "Bucket not found or already empty"

# Delete the bucket
aws s3api delete-bucket --bucket $BUCKET_NAME --region $AWS_REGION 2>/dev/null || echo "Bucket not found or already deleted"

echo "S3 model cache bucket deleted!"
EKS 노드 그룹 삭제하기
AWS Cloudformation에 접근 후 노드그룹 스택 종료 방지를 제거한 이후
삭제를 실행시켜주세요.
#
kubectl delete ns ingress-nginx
kubectl delete -n kube-system ds/s3-csi-node
kubectl delete -n kube-system ds/neuron-device-plugin

#
kubectl delete -n kube-system deploy/k8s-neuron-scheduler
kubectl delete -n kube-system deploy/my-scheduler
kubectl delete -n kube-system deploy/s3-csi-controller
kubectl delete -n kube-system deploy/metrics-server

# 노드 그룹 제거
eksctl delete --cluster ai-infra-summit-test-cluster nodegroup neuron-trn1-2x
더 살펴보기
(AWS Workshop) Generative AI on Amazon EKS 에 대해 살펴볼 예정입니다.